
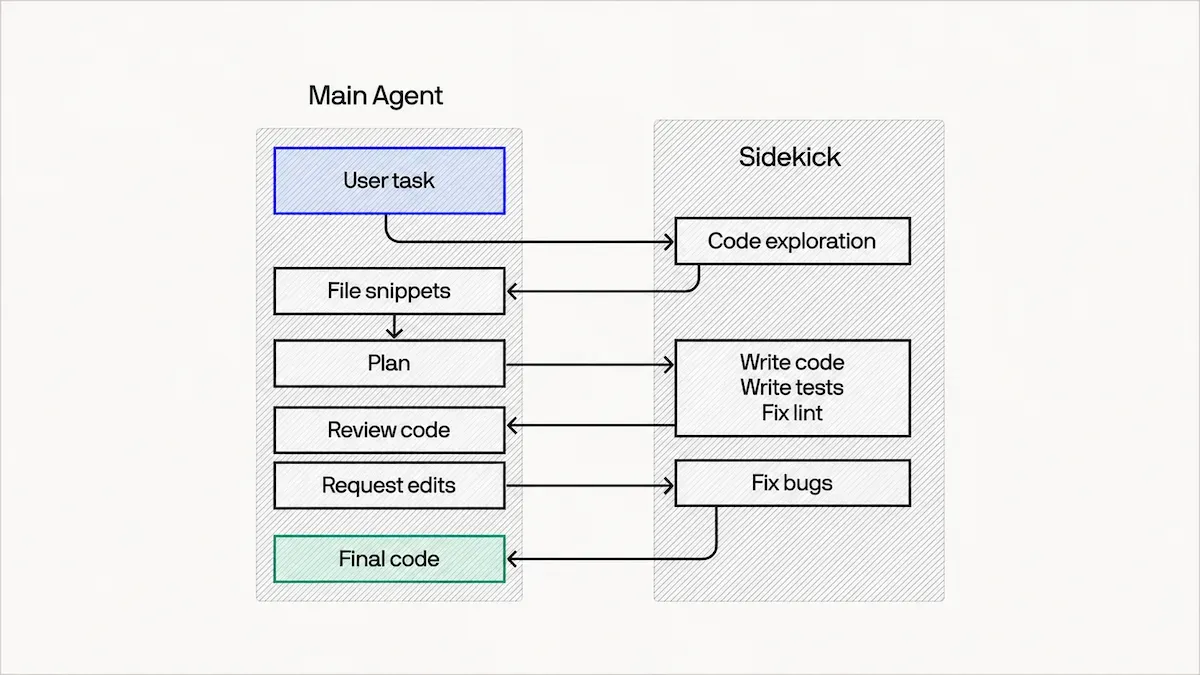
Devin Fusion Matches Claude Fable 5.1 and GPT-6 Astra Performance At Lower Costs
Benchmarking a coding agent typically means scoring one model within one harness.
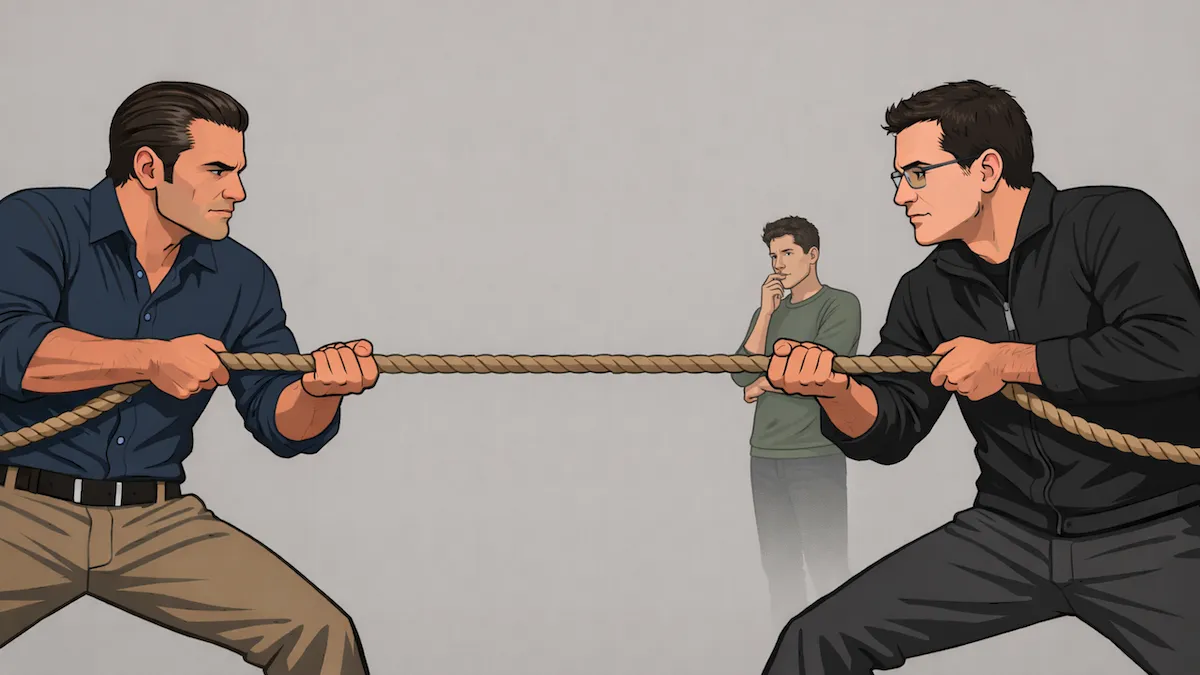 Secretary of War Pete Hegseth Calls Claude a Security Risk, Replaces It With GPT Modelsdeeplearning.ai
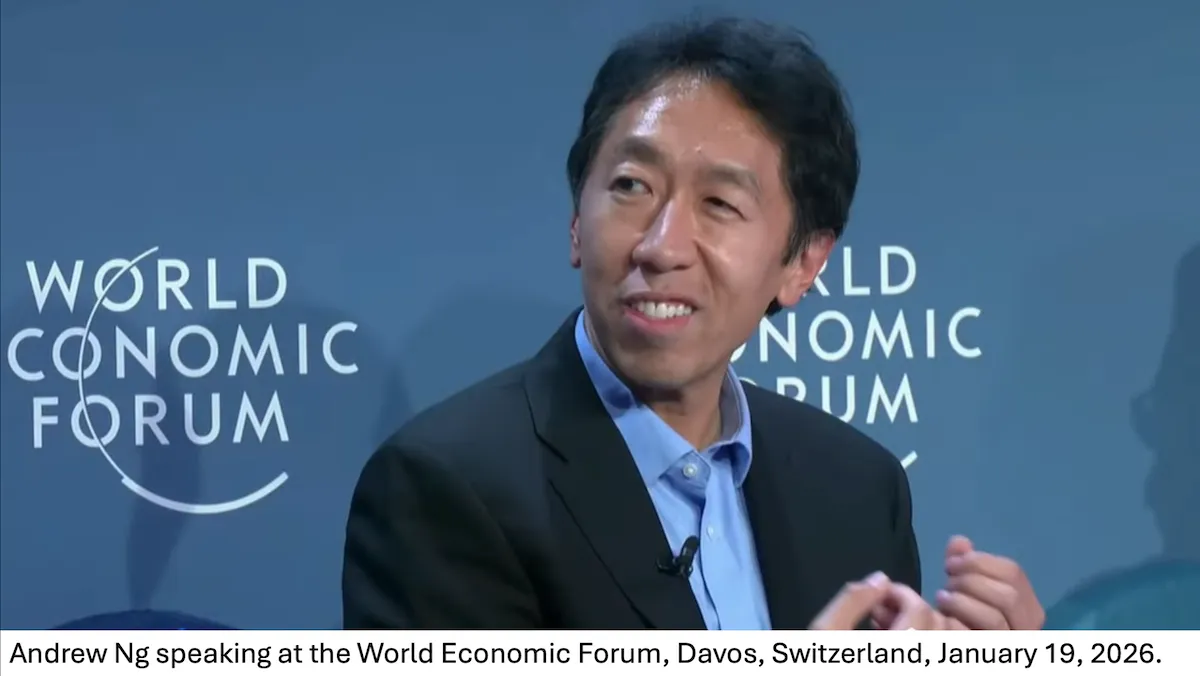 From AI Experiments to AI Productsdeeplearning.ai
 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
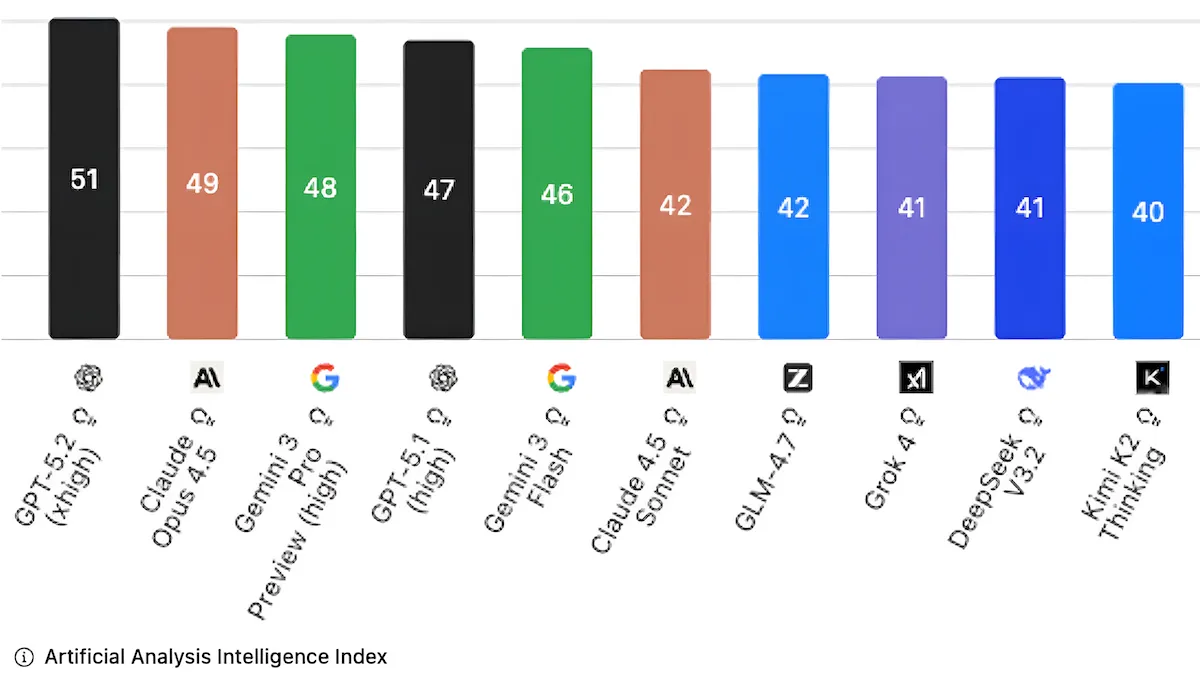 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
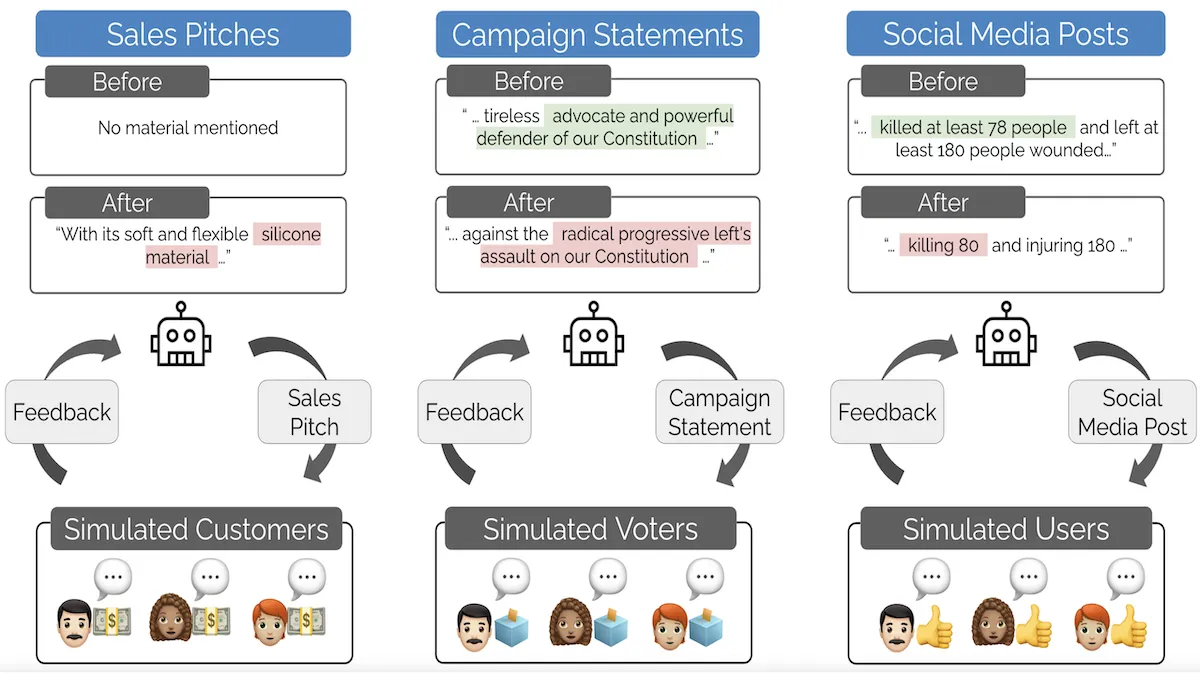 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
 Data Points: The latest in AI from Mar. 21 to Mar. 27, 2024deeplearning.ai
 The Proven Redis PerformanceRedis
 From Automation Veteran to AI Pioneer: How Evan Nison transformed his agency with Zapier MCPZapier
 How a top tier European soccer team sped up their data processing and reduced costs by 50%Modal
 How to serve trillions of tokens for trillion-parameter coding agentsModal
 Anthropic integration with Modal brings scalable compute to Claude ScienceModal
 Product updates: Datadog integration, lower function latency & moreModal
 Jetpack Boost Handles Critical CSS For YouCss Tricks
 Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Real-Time Computational Physics with Wafer-Scale Processing [updated]Cerebras
 Accelerating GPT-5.6 Sol UltrafastCerebras
 AI's Role in Video Marketing, Cost EfficiencyHeygen
 Meta AI Video Generator's ImpactHeygen
 How the world’s biggest YouTuber served millions of users on VercelVercel
 The Noise Reduction Paradox in Speech-to-Text AccuracyDeepgram
