
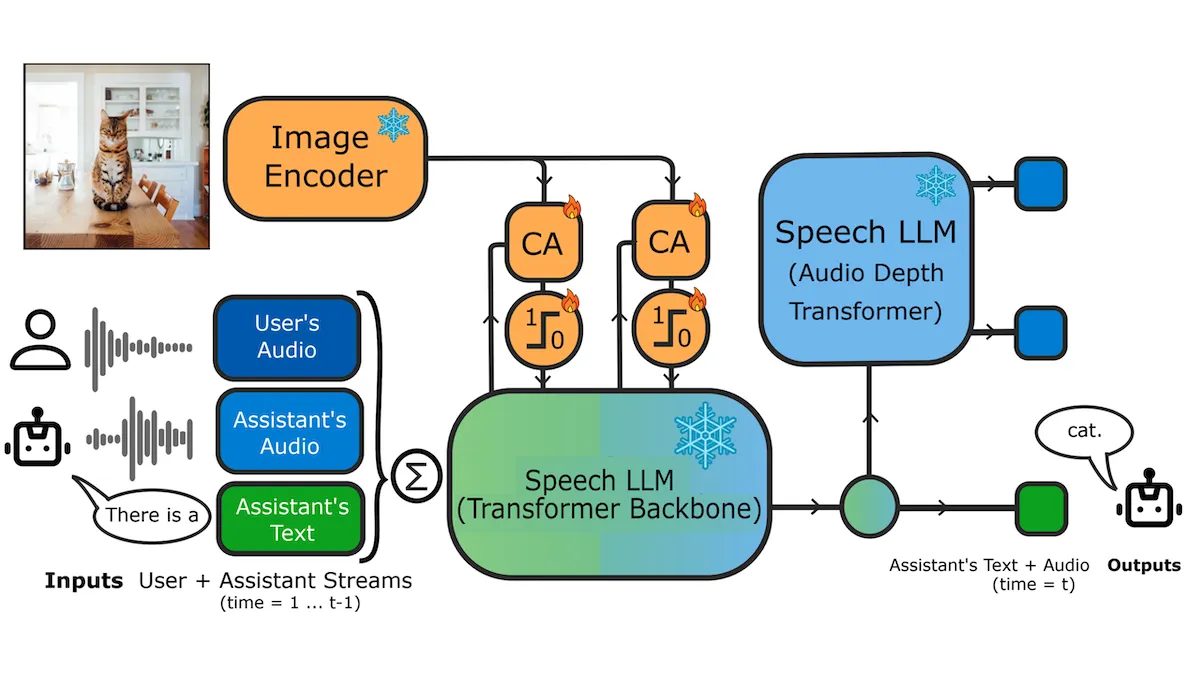
MoshiVis Adds Image Understanding to Voice-First Conversations
Researchers updated the highly responsive Moshi voice-to-voice model to discuss visual input.
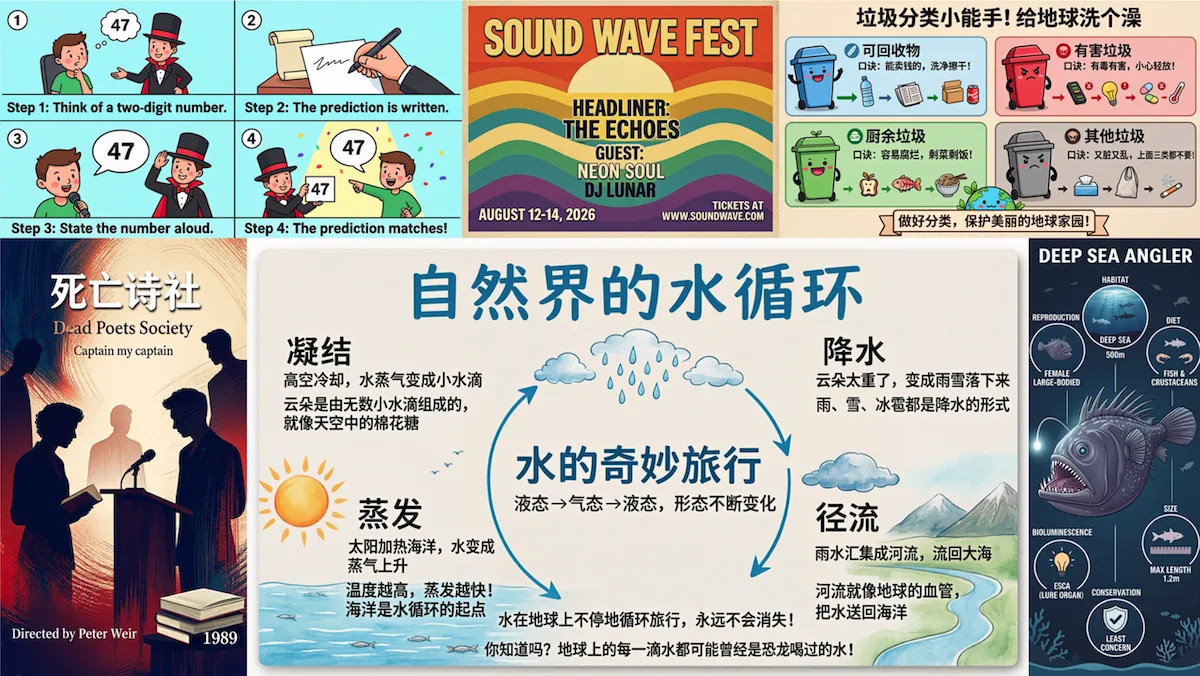 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
 From AI Experiments to AI Productsdeeplearning.ai
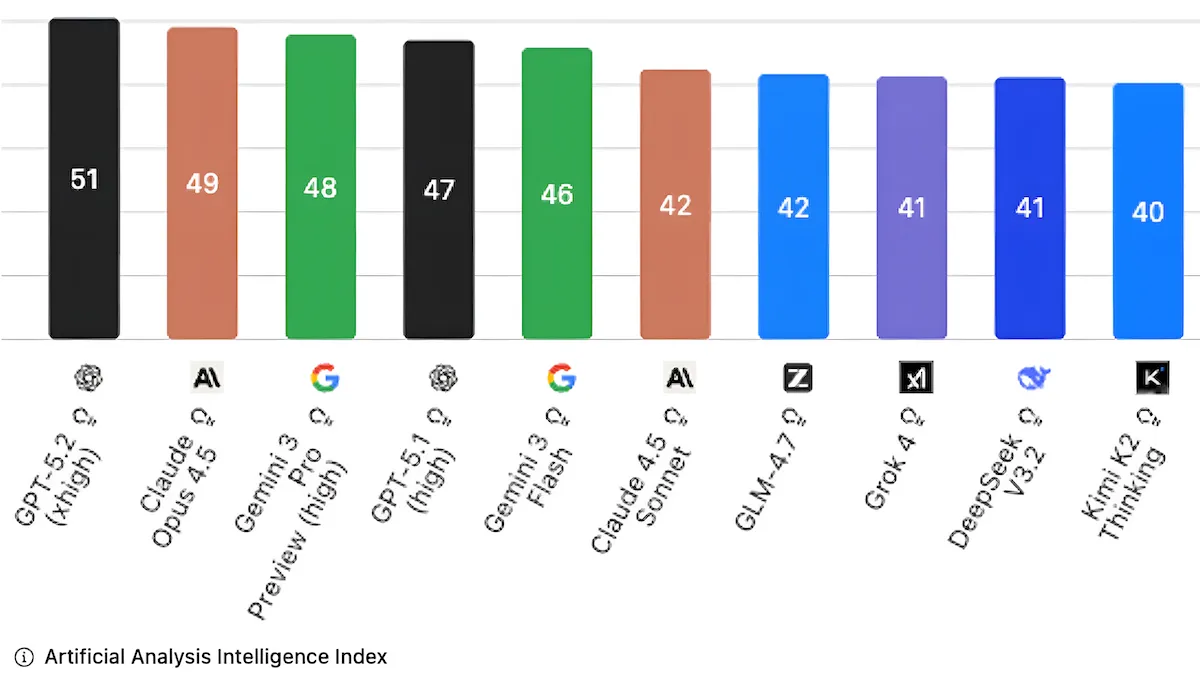 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
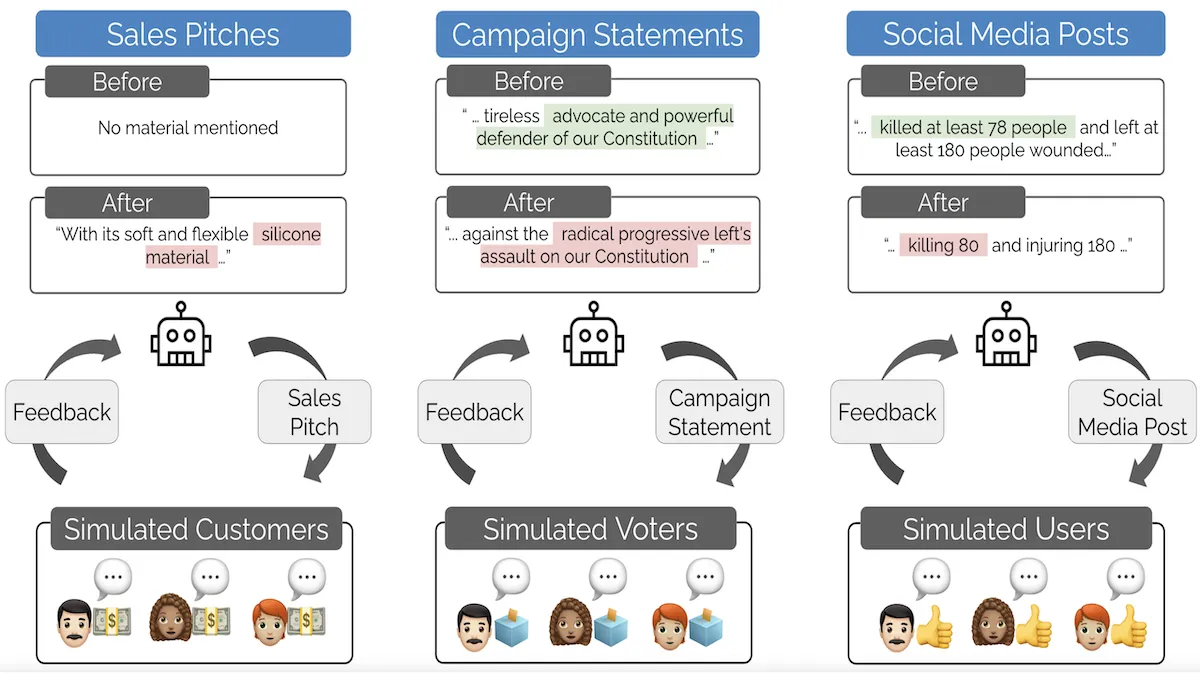 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
 Secretary of War Pete Hegseth Calls Claude a Security Risk, Replaces It With GPT Modelsdeeplearning.ai
 Data Points: The latest in AI from Mar. 21 to Mar. 27, 2024deeplearning.ai
 Playing With P5.js: Creating a Voice-Controlled Game - Deepgram Blog ⚡️Deepgram
 The Language of LGBTQ Inclusion and Allyship - Deepgram Blog ⚡️Deepgram
 The Simplest Possible Neural Network, Explained - Deepgram Blog ⚡️Deepgram
 Calling Your Video Game With Your Phone: Part 1Deepgram
 The Best (and Worst?) of Voice AI TechnologyDeepgram
 No Code Transcription: Simplifying Workflows with Deepgram and Make.comDeepgram
 Q&A with Deepgram’s New CPO, Ed AnuffDeepgram
 Automate Audio Transcription with Zapier + DeepgramDeepgram
 The App Engine SDK and workspaces (GOPATH) - The Go Programming LanguageGo
 How Hunch supercharged AI workflows with Modal SandboxesModal
 Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Cerebras Systems Enables GPU-Impossible™ Long Sequence Lengths Improving Accuracy in NaturalCerebras
Memo-ry: Simplifying Daily Tasks for People with Memory Loss - CerebrasCerebras
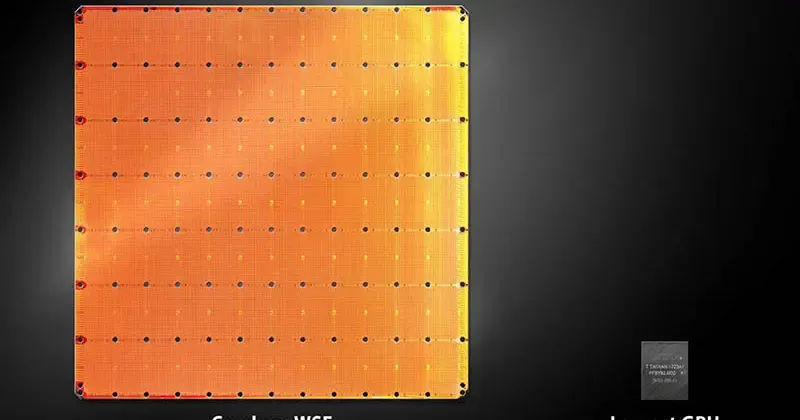 Cerebras Systems Unveils the Industry’s First Trillion Transistor Chip - CerebrasCerebras
