
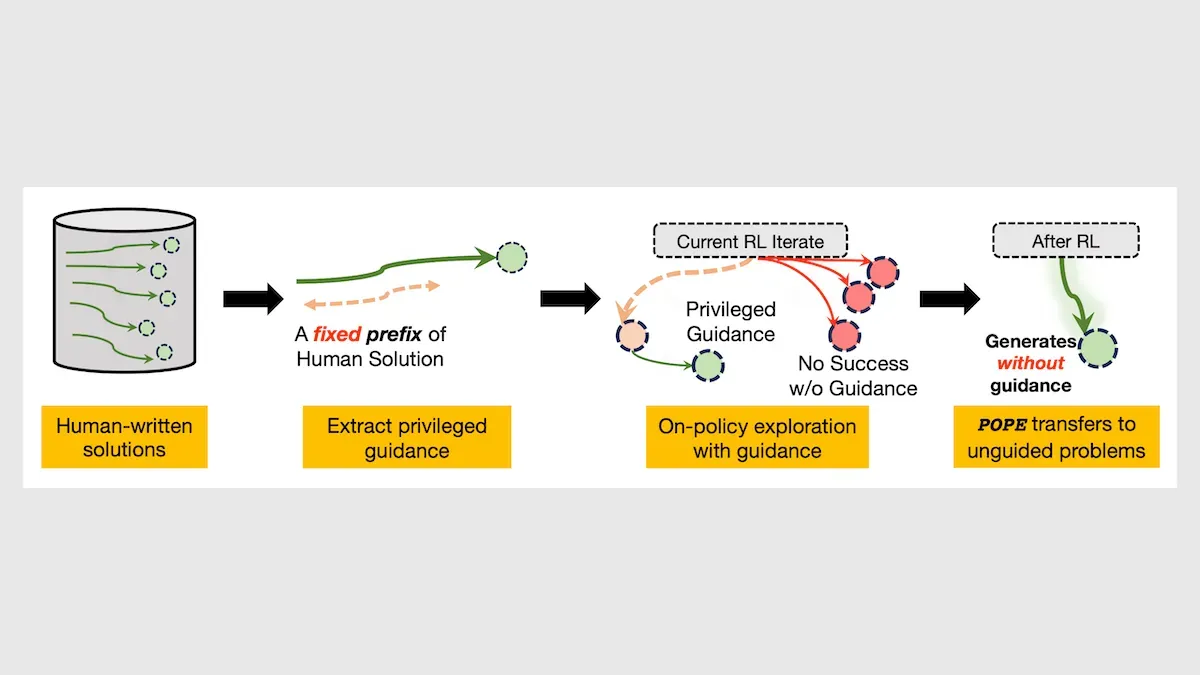
Privileged On-Policy Exploration (POPE) Trains Models To Expand on Partial Solutions
Reinforcement learning can’t train a model to solve a difficult problem if the model doesn’t discover all the right steps.
 Secretary of War Pete Hegseth Calls Claude a Security Risk, Replaces It With GPT Modelsdeeplearning.ai
 From AI Experiments to AI Productsdeeplearning.ai
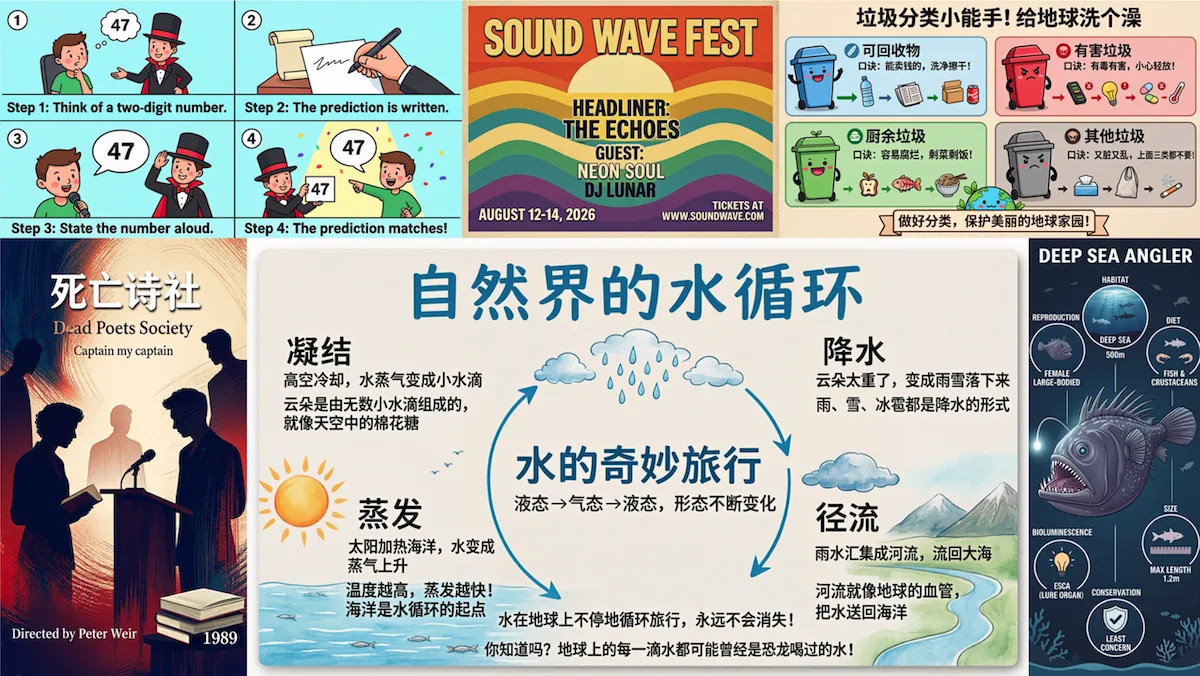 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
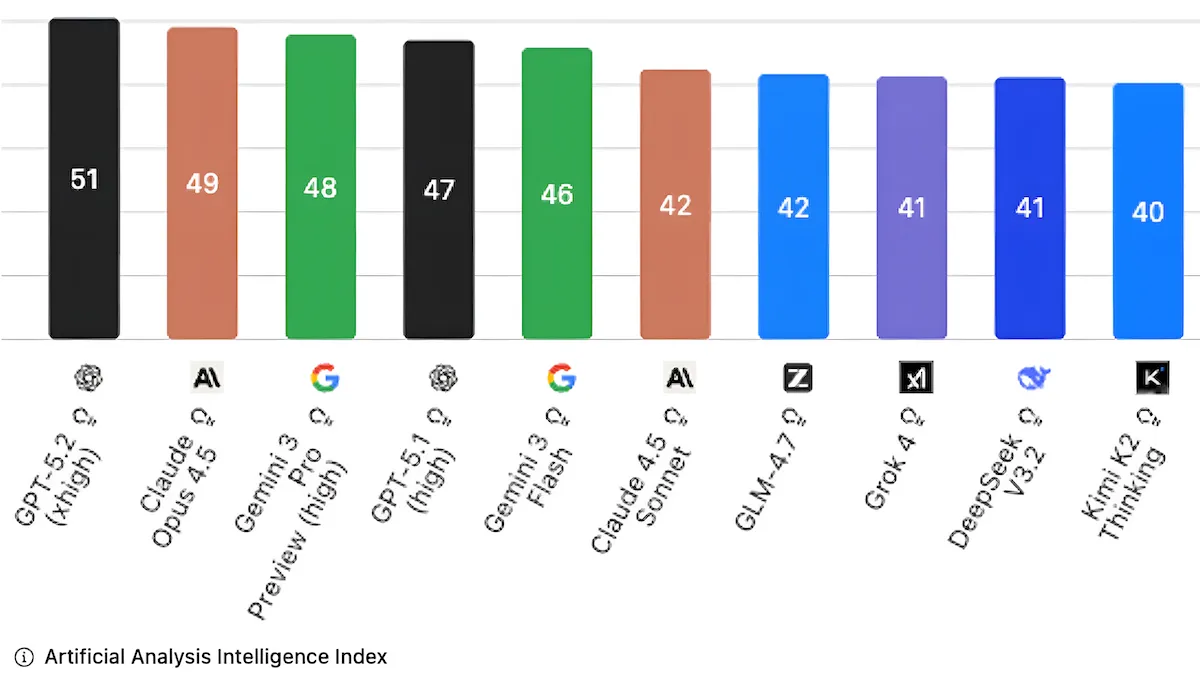 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
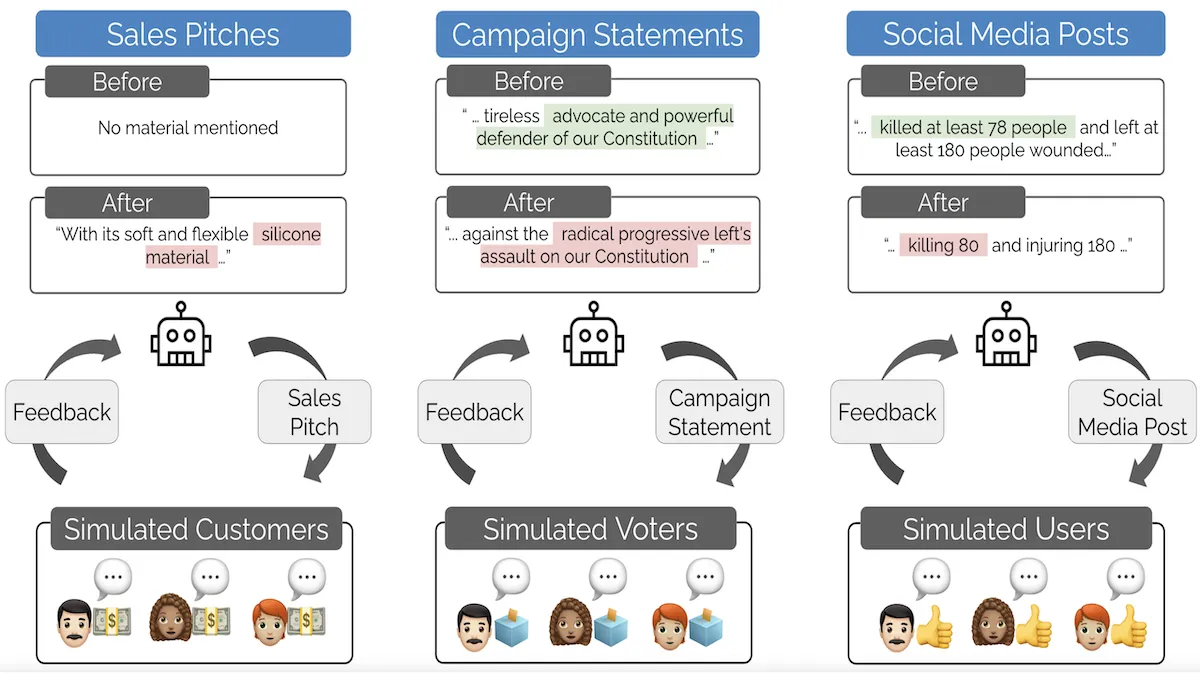 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
 Data Points: The latest in AI from Mar. 21 to Mar. 27, 2024deeplearning.ai
 A Guide to Extended Threat Detection and Response: What It Is and How to Choose the Best SolutionsCybersecurity Exchange
 Docs-as-code solutions for API teams: how to choose the right platform in 2026Mintlify
 10 best AI observability tools for monitoring and evaluating agents in 2026Mintlify
 New Spanish and Turkish Language Models and Updated General Models - Deepgram Blog ⚡️Deepgram
 AI frameworks: Definition, types, and how to chooseZapier
 Empower Your Team with Policy as CodePulumi
 Discovered Stacks: One Place for All Your InfrastructurePulumi
 New Policy as Code Capabilities with CrossGuardPulumi
 Go Wiki: PortingPolicy - The Go Programming LanguageGo
 How Hunch supercharged AI workflows with Modal SandboxesModal
 Anthropic integration with Modal brings scalable compute to Claude ScienceModal
 Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Cerebras Systems Enables GPU-Impossible™ Long Sequence Lengths Improving Accuracy in NaturalCerebras
 How to Run Hugging Face Models Programmatically Using Ollama and TestcontainersDocker
