
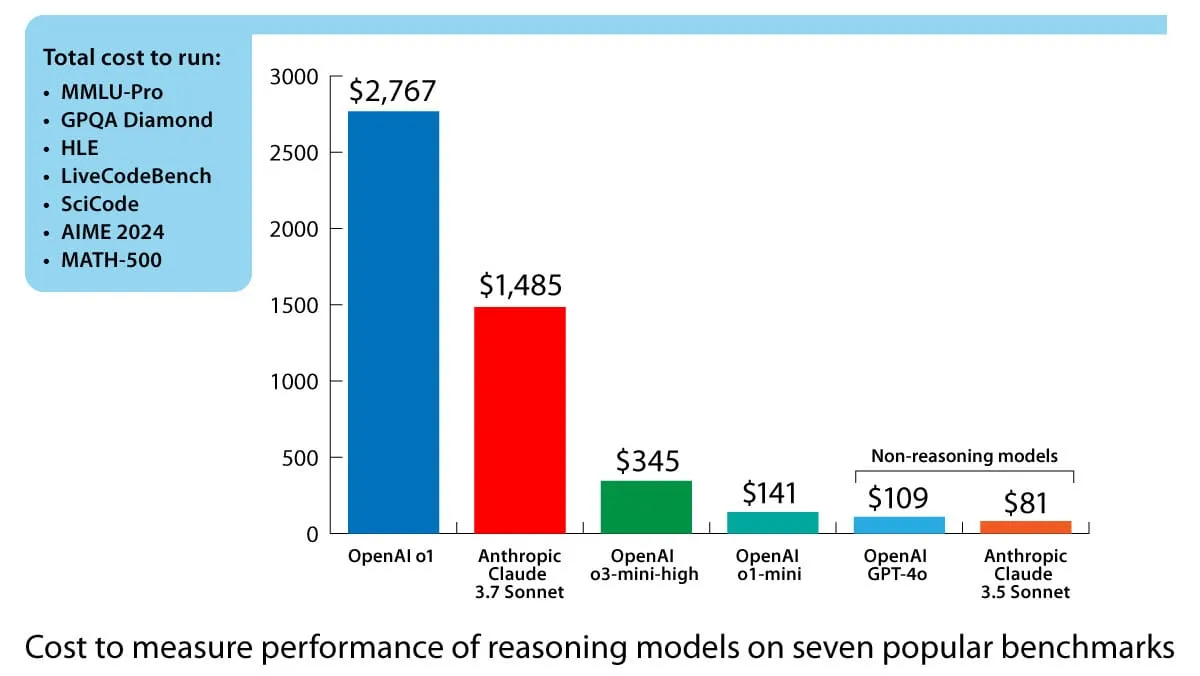
Reasoning LLMs Are Pricey to Test
An independent AI test lab detailed the rising cost of benchmarking reasoning models.
 FactTune, A Method to Fine-Tune LLMs for Factual Accuracy Without Human Feedbackdeeplearning.ai
 From AI Experiments to AI Productsdeeplearning.ai
 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
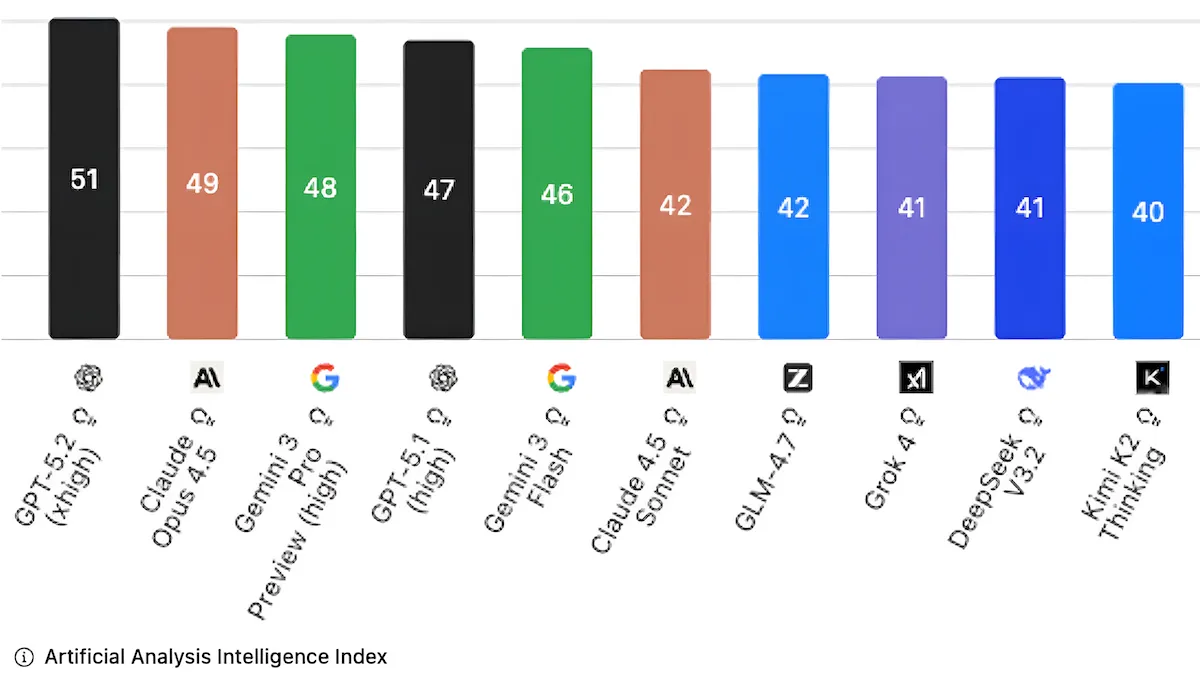 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
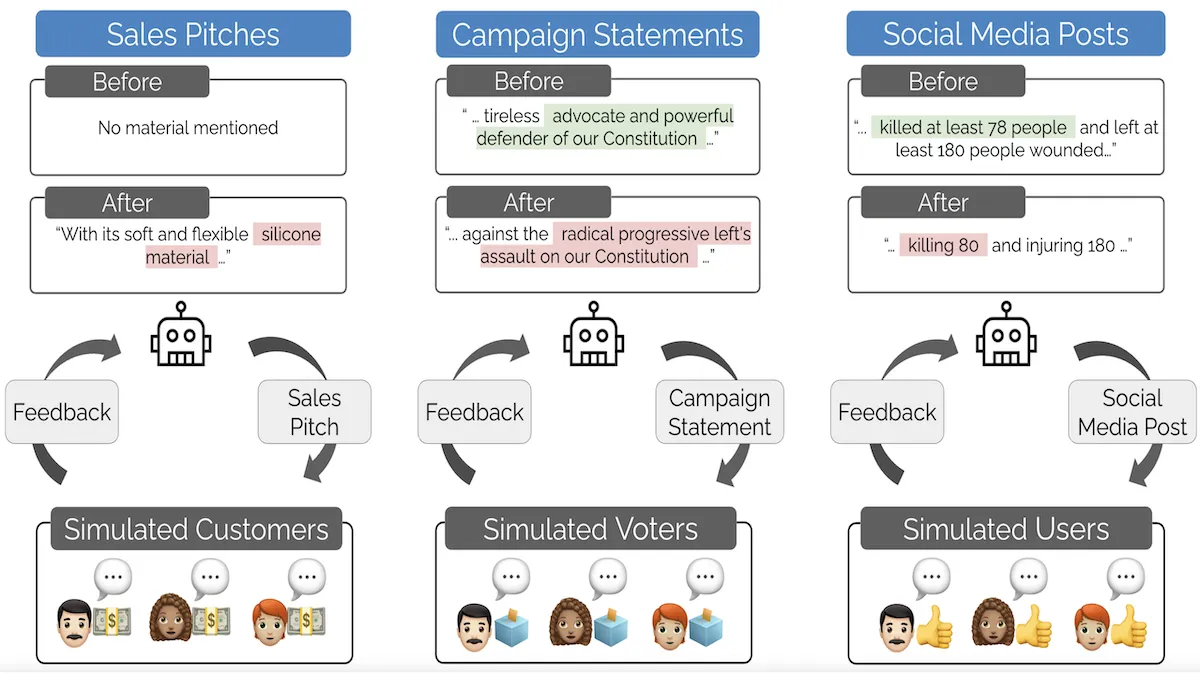 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
 Secretary of War Pete Hegseth Calls Claude a Security Risk, Replaces It With GPT Modelsdeeplearning.ai
 Grafana Is Not Worried About AWS CommercializationThenewstack
 Supporting Kubernetes with Faster, Easier Test EnvironmentsPulumi
 How Ramp automated receipt processing with fine-tuned LLMsModal
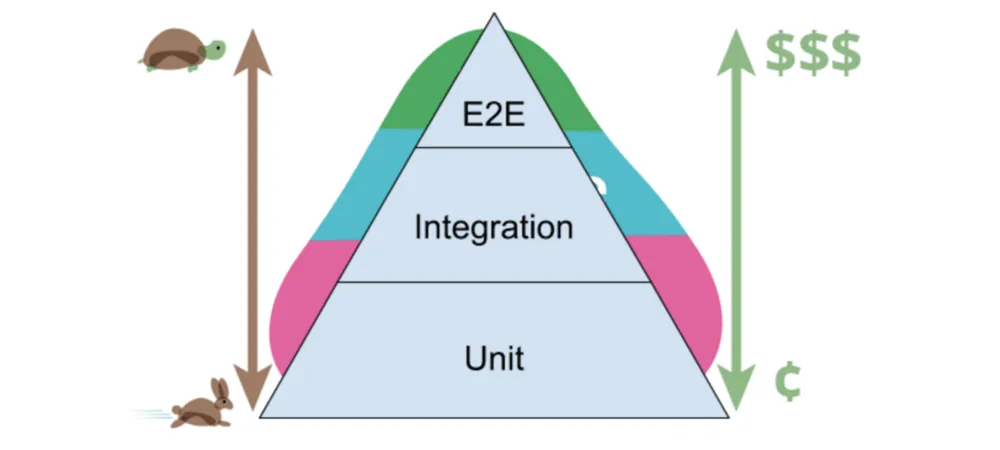 Develop, Preview, TestCss Tricks
 How AI Assistants Can Decode GitHub Repos for UI WritersDocker
 Calendly vs. Acuity: Which is best? [2026]Zapier
 Anthropic Identifies Biased Reasoning and Recklessness as Drivers of Claude’s PyPI AttackSocket
 Automate API tests and Debug in Docker with Postman’s NewmanDocker
 Bunny Network Tools are here. Test away at bunny.net!Bunny
 How to structure documentation for both AI and human readersMintlify
 Mintlify CLI - MintlifyMintlify
 SuperGLUE: Understanding a Sticky Benchmark for LLMsDeepgram
 ChatGPT: Putting the “AI” in “Plagiarism” worldwide?Deepgram
 What is RetoolGPT? How we built an internal AI assistantRetool
