
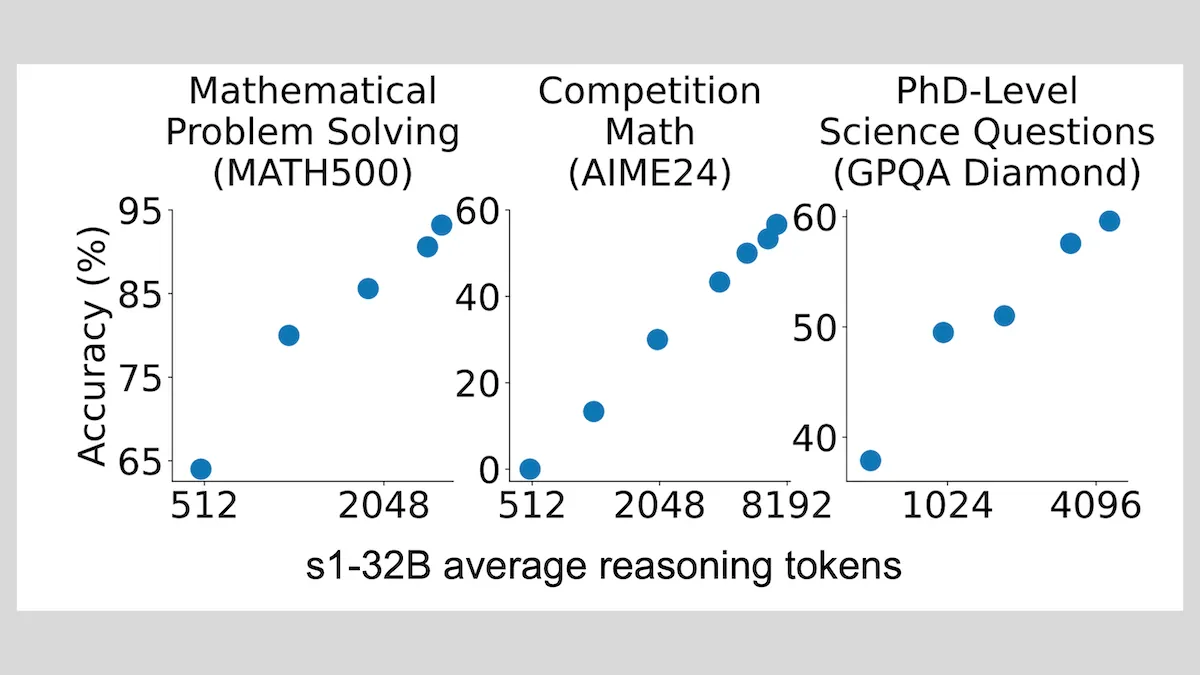
Researchers Fine-Tune LLM for Reasoning with Only 1,000 Examples
Researchers showed that supervised fine-tuning on as few as 1,000 examples can enable a pretrained large language model to reason — and a clever...
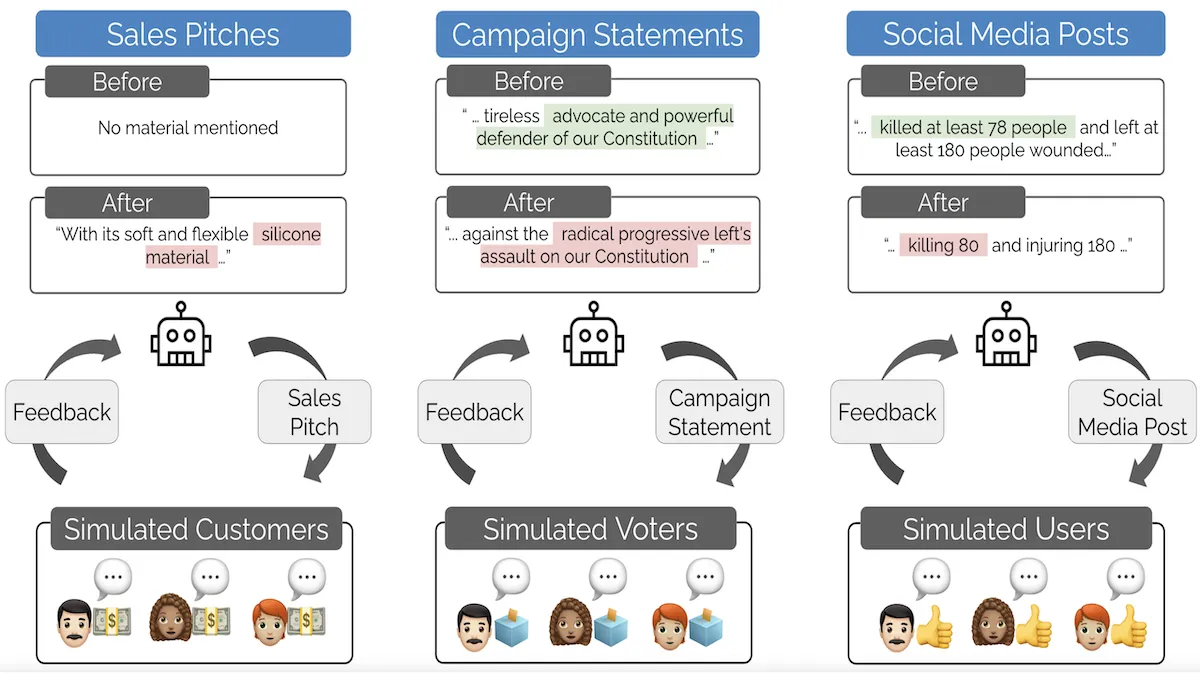 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
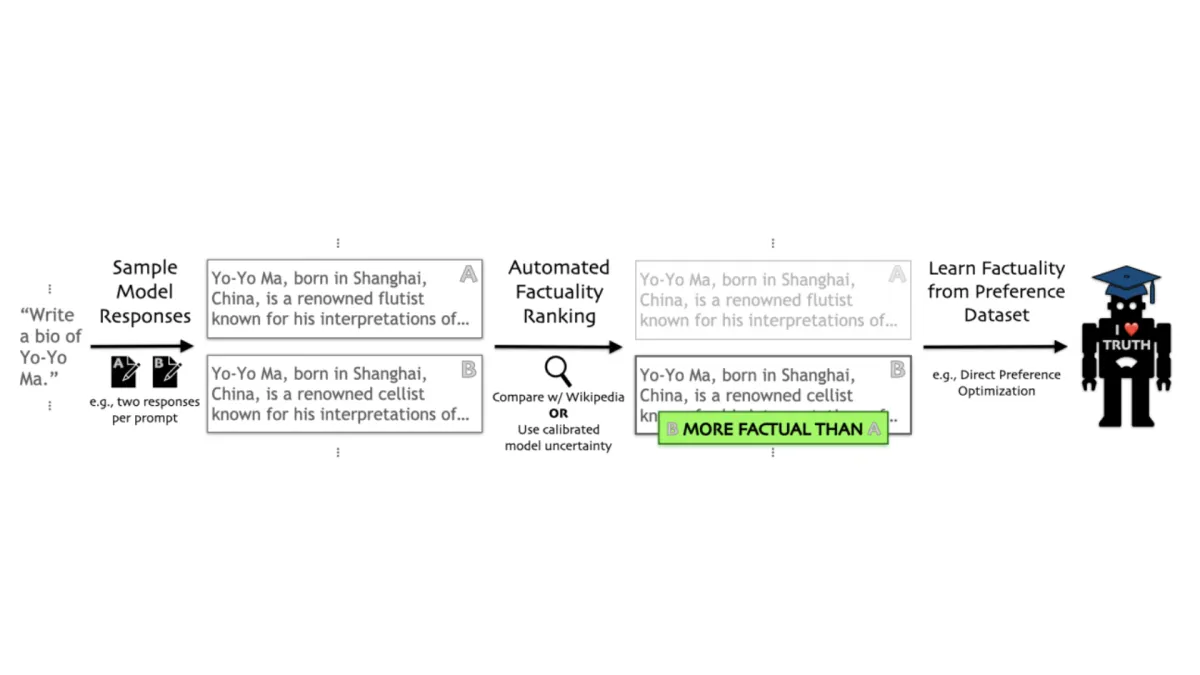 FactTune, A Method to Fine-Tune LLMs for Factual Accuracy Without Human Feedbackdeeplearning.ai
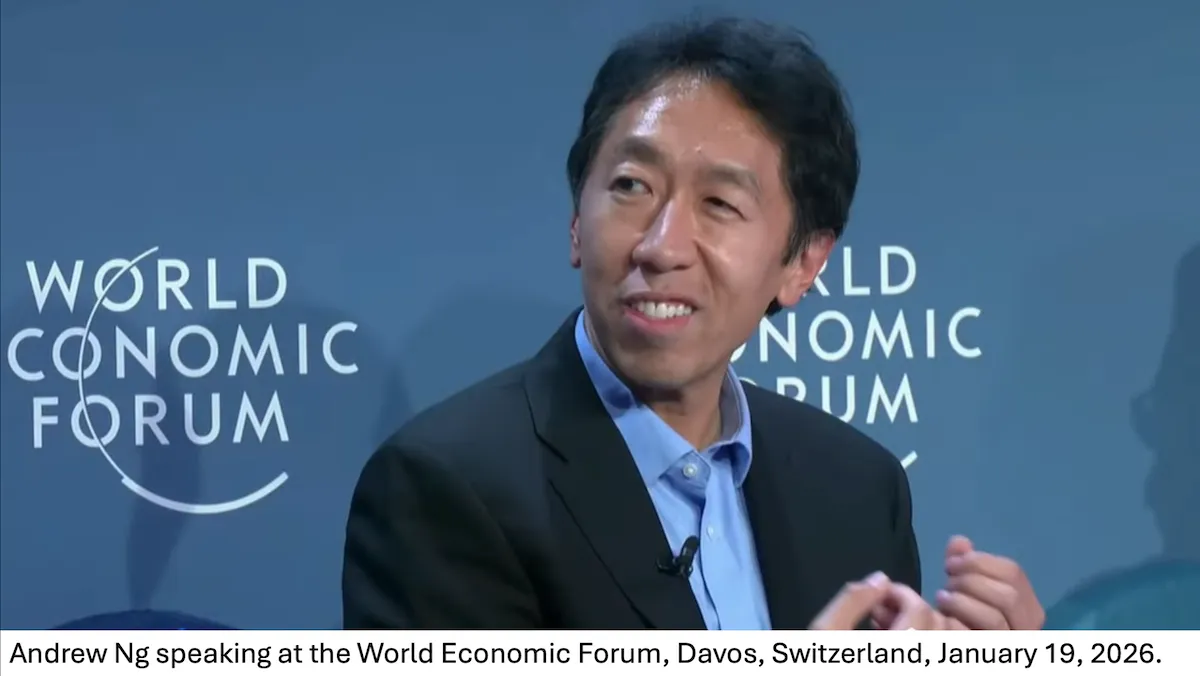 From AI Experiments to AI Productsdeeplearning.ai
 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
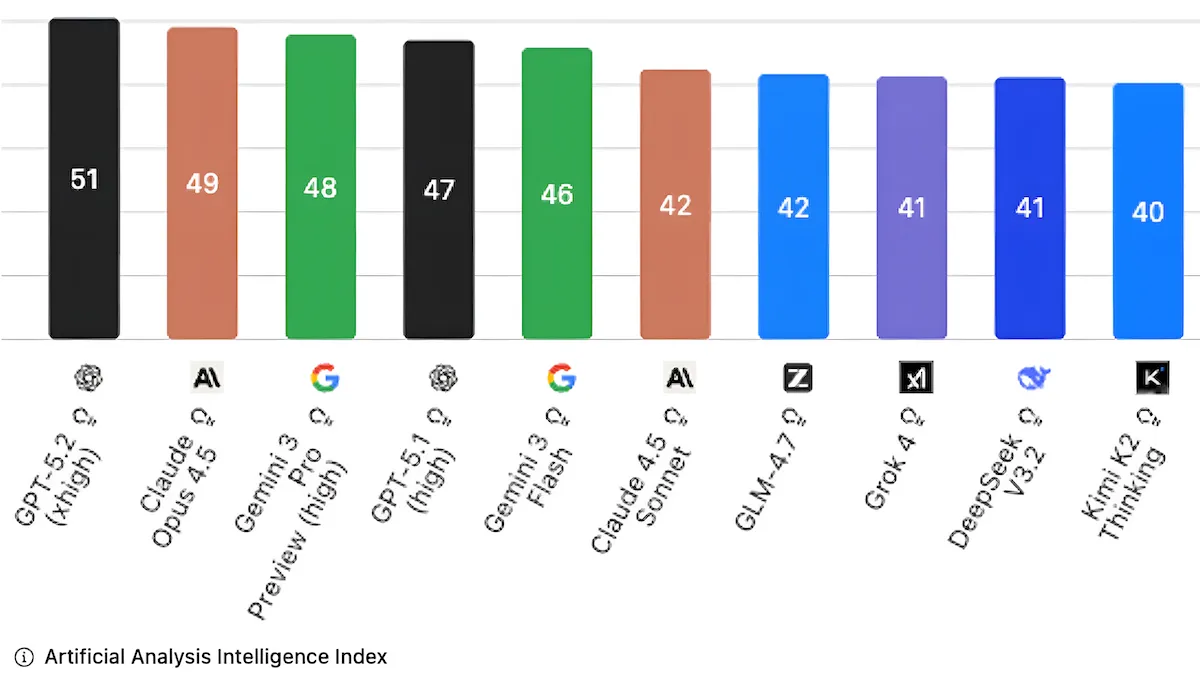 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
 Secretary of War Pete Hegseth Calls Claude a Security Risk, Replaces It With GPT Modelsdeeplearning.ai
 Trained on 100,000+ Voices: Deepgram Unveils Next-Gen Speaker Diarization and Language DetectionDeepgram
 How Ramp automated receipt processing with fine-tuned LLMsModal
 Anthropic integration with Modal brings scalable compute to Claude ScienceModal
 Building a Remote MCP Server: OAuth, Tool Design & Lessons from 4,000+ AI Queries | MotherDuckMotherduck
 PostgreSQL and Ducks: The Perfect Analytical PairingMotherduck
 KAUST and Cerebras Named Gordon Bell Award Finalist for Solving Multi-Dimensional SeismicCerebras
 You can just ship agentsVercel
 Write effective prompts - MintlifyMintlify
 Anthropic Identifies Biased Reasoning and Recklessness as Drivers of Claude’s PyPI AttackSocket
 Twitch Browser Extension Exposes 30,000 Users’ OAuth Tokens to Russian Bot ServiceSocket
 GlassWorm Loader Hits Open VSX via Developer Account CompromiseSocket
 737 Chrome VPN Extensions Linked to Brand Impersonation and Browser Traffic RedirectionSocket
 Product updates: Running batch jobs with 1M inputs, ephemeral apps, and a new TensorRT-LLM exampleModal
 Beating proprietary models with a quick fine-tuneModal
