
The Problem with Benchmark Contamination in AI
The universe of web pages includes correct answers to common questions that are used to test large language models. How can we evaluate new models...
 From AI Experiments to AI Productsdeeplearning.ai
 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
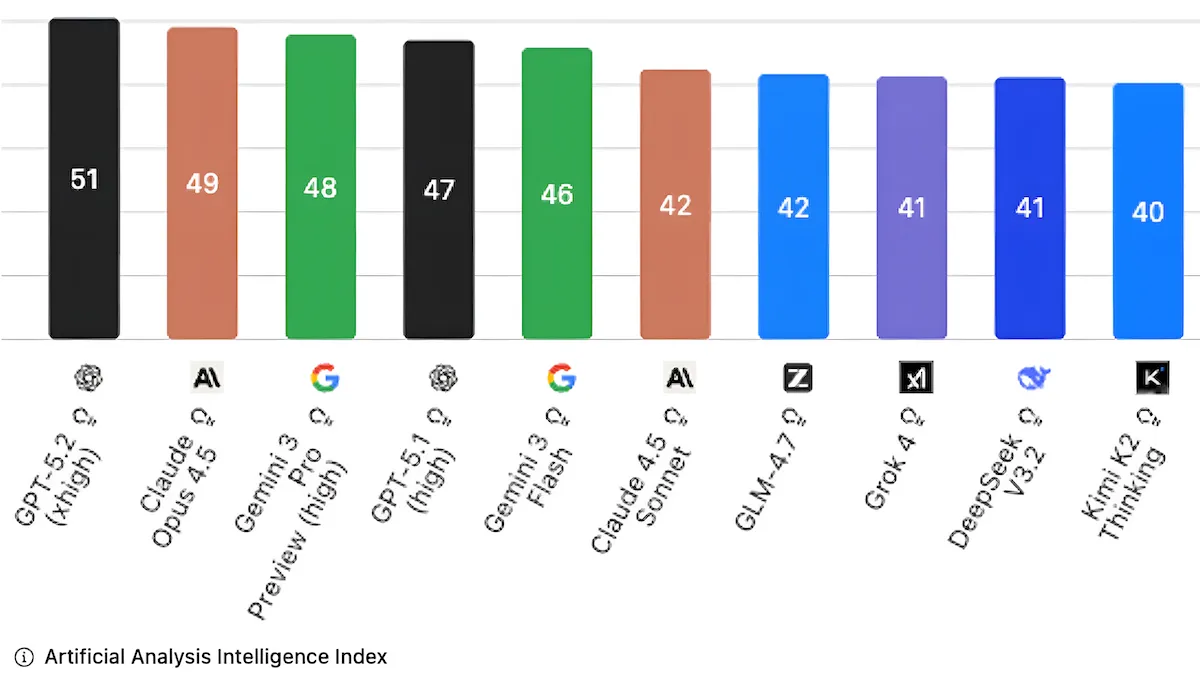 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
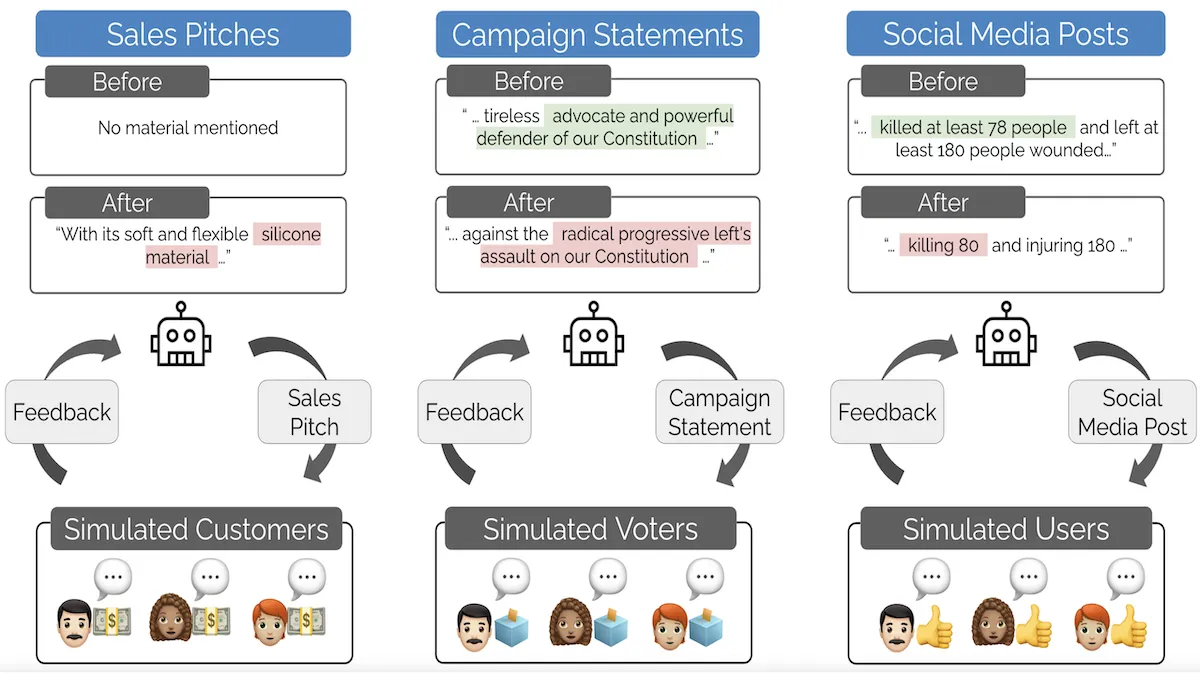 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
 Secretary of War Pete Hegseth Calls Claude a Security Risk, Replaces It With GPT Modelsdeeplearning.ai
 Data Points: The latest in AI from Mar. 21 to Mar. 27, 2024deeplearning.ai
 Oso Unbundles Security AuthorizationThenewstack
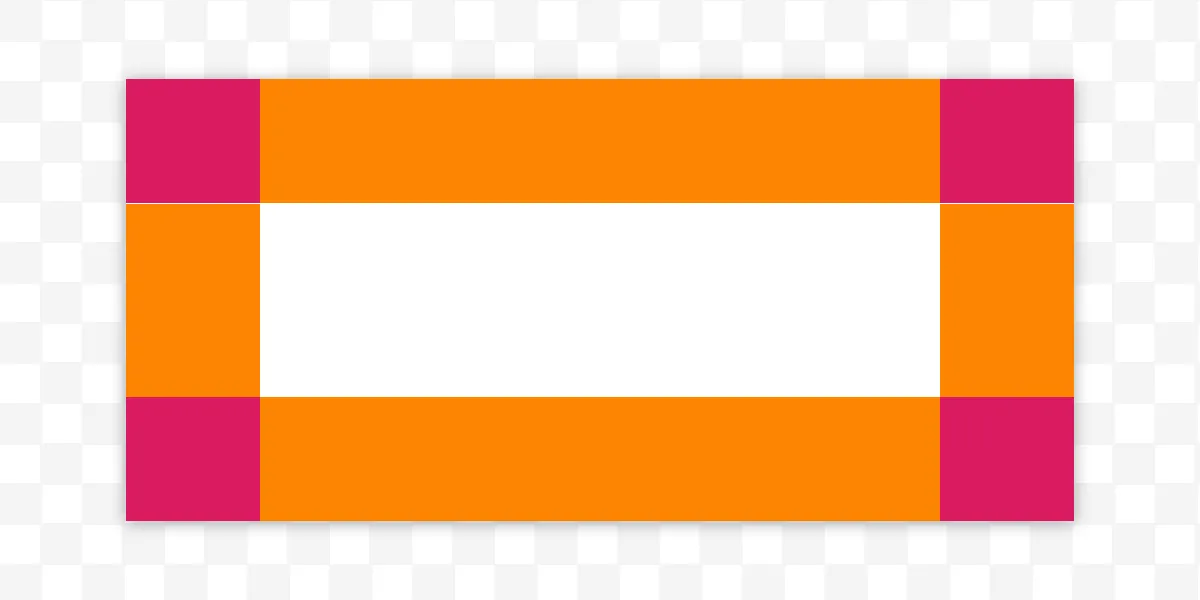 Some Things You Oughta Know When Working with Viewport UnitsCss Tricks
 MotherDuck Builder Office Hours - July 21Motherduck
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Lies, damn lies, and benchmarksDeepgram
 Troubleshooting .NET automatic instrumentation issuesOpentelemetry
 What is Root Cause Analysis?Datadoghq
 SuperGLUE: Understanding a Sticky Benchmark for LLMsDeepgram
 The Problem with Transatlantic Data TransfersThenewstack
 Beyond API Security Testing: Runtime ProtectionThenewstack
 GPU autoscaling on Kubernetes with KEDA: Building an external scalerCncf
 IBM, Red Hat Bring Load-Aware Resource Management to KubernetesThenewstack
 Measuring CI/CD Adoption Rates Is a ProblemThenewstack
 Elastic at Gartner IT Symposium/Xpo 2025 BarcelonaElastic
