
Run Gomplate Prompt Templating against gpt-oss:20b Locally with Ollama
Build one prompt, run it anywhere. Learn to create a unified workflow that sends templated prompts to Claude or a local model with Ollama for max flexibility.
 Run Gomplate Prompt Templating against gpt-oss:20b Locally with Ollamaegghead.io
 Build up Reusable Claude Code Workflows with Dynamic Prompt Templating using Gomplateegghead.io
 Control the Exact Context You Give Claude Code with Repomix and Gomplate Pluginsegghead.io
 Capture: Transforming Cursor AI Conversations into Persistent Knowledgeegghead.io
 Streamline: Automating Cursor History Export with CLI Toolsegghead.io
 Extract: Mining AI Insights from Chat Logs with MCP-Powered Analysisegghead.io
 Trigger automation - MintlifyMintlify
 Sidecars: A low-latency trust boundary for SandboxesModal
 CLI ReferenceModal
 Anthropic integration with Modal brings scalable compute to Claude ScienceModal
 Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Accelerating GPT-5.6 Sol UltrafastCerebras
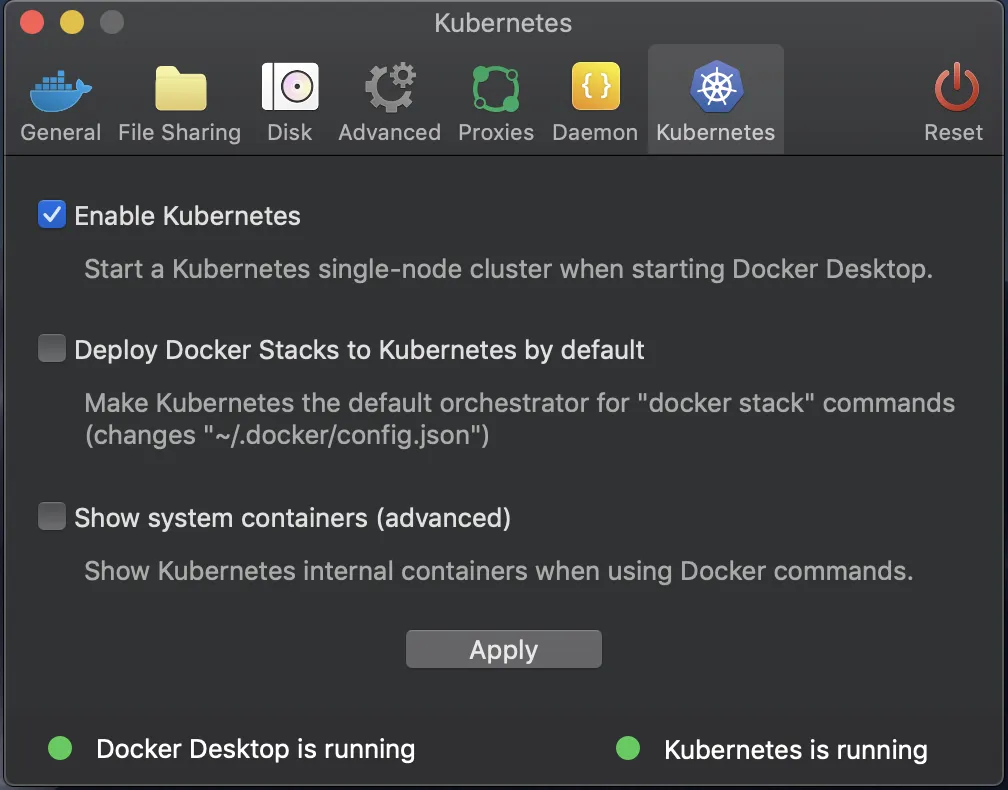 Depend on Docker for KubeflowDocker
 How to Run Hugging Face Models Programmatically Using Ollama and TestcontainersDocker
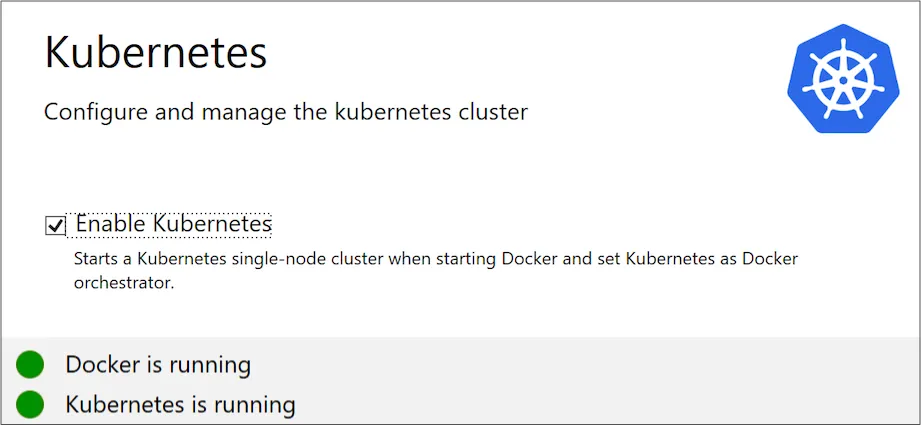 Docker for Windows Desktop with KubernetesDocker
 A prompt guide to get the most out of HeyGen's new Video AgentHeygen
 Preview locally - MintlifyMintlify
 Breakdown: The Kubernetes-Run AI Video Generation Pipeline for NIUS.TVThenewstack
 Run GPU jobs from Airflow with ModalModal
 How Contextual AI automated CI with Modal GPUsModal
