
Dedicated Endpoints
Dedicated Endpoints run any model in the Modal Library, or custom weights, on isolated, autoscaling containers.
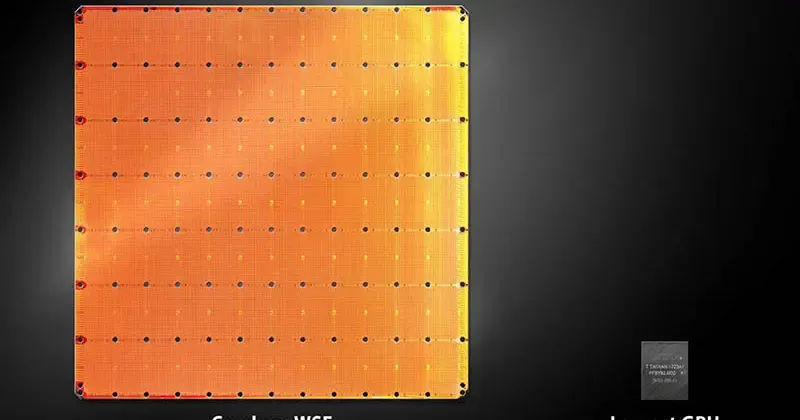 Cerebras Systems Unveils the Industry’s First Trillion Transistor Chip - CerebrasCerebras
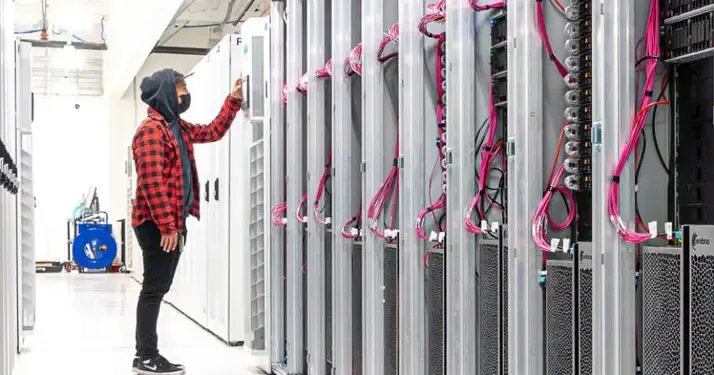 The Cerebras AI Model Studio brings Wafer-Scale Cluster Acceleration to the Cloud - CerebrasCerebras
 Troubleshooting - MintlifyMintlify
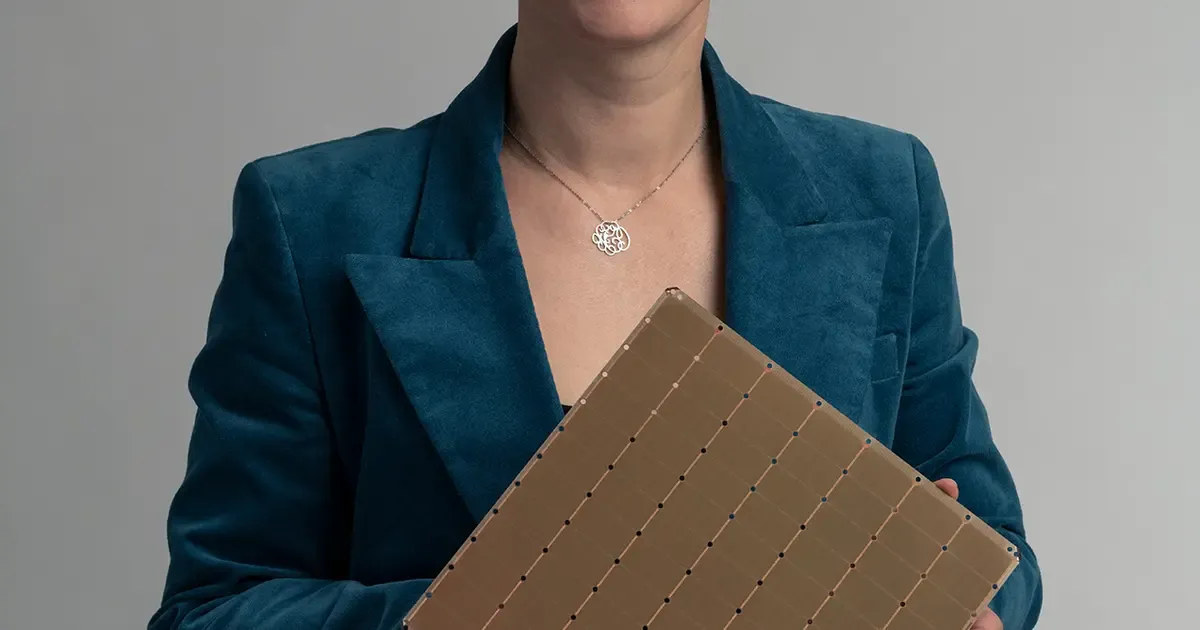 Cerebras Systems Smashes the 2.5 Trillion Transistor Mark with New Second Generation Wafer ScaleCerebras
 Multiple responses - MintlifyMintlify
 Cerebras Announces Fine-Tuning on the Cerebras AI Model Studio - CerebrasCerebras
 How to Give Your AI Agents Reliable App Access for FreeZapier
 Inference at Scale with Dedicated DeploymentsBaseten
YC Startup Deal: Up to $50,000 in Credits | falFal
Topaz Video AI & Image Upscaling APIFal
 Make a dedicated Wake-on-LAN server with TailscaleTailscale
Enhanced Log Streaming: Private Endpoints, Cribl Support, and Audit Logs for Free PlansTailscale
 DNS redundancy with Netlify’s dedicated DNS networkNetlify
DeepSeek V4 Pro: Validating Frontier Models for ProductionFireworks
