

arXiv:2610.40250v1 Announce Type: new Abstract: We revisit advantage estimation in Group Relative Policy Optimization (GRPO) and observe that any token-level advantage admits a two-stage factorization: a \emph{sample-level baselining} step that converts scalar verifier rewards into a comparable sequence-level signal, and a \emph{token-level credit assignment} step that distributes that signal over the trajectory.
Recommended
 Reward-Adaptive Co-Evolution of Policy and RubricarXiv cs.AI
Amortized Localized Posterior Inference for Model Calibration with Application to an Ocean…arXiv cs.AI
FLORO: A Multimodal Geospatial Foundation Model for Ecological Remote Sensing Across Sensors and…arXiv cs.AI
Multistep and Multivariate Time Series Explainability with GradientSHAP: A Wind Power Case StudyarXiv cs.AI
Ramanujan Challenge Results: AI-Assisted Evaluation Pipeline for Multi-Format ProofsarXiv cs.AI
EHRNote-ChatQA: A Benchmark for Evidence-Grounded Multi-Turn Clinical Question Answering over…arXiv cs.AI
 Credit pricing - MintlifyMintlify
 Synthesia launches talent experience program to learn from and reward the exceptional actors behindSynthesia
 Gemma 4 on Cerebras—The Fastest Inference is Now MultimodalCerebras
 Kimi K3 by Moonshot now available on ModalModal
 Best AI Video Generators 2026: 12 Tools Tested & RankedHeygen
 11 Best Akool Alternatives & Competitors Picked For 2026Heygen
 Be Like Switzerland: 6 New Service Mesh StandardsThenewstack
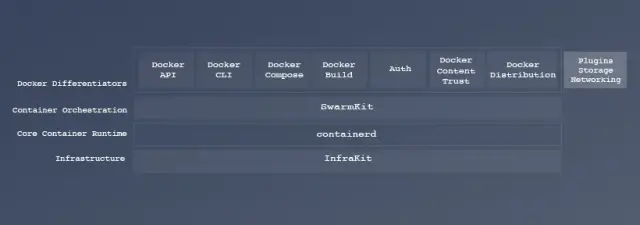 containerd - a core container runtime project for the industryDocker
 EMEA - Webinar: Get AI Spend Under Control1password
 Seedance 2.5 AI Video GeneratorFal
 Seedream 5.0 Pro API - Multimodal AI Image ModelFal
 Gemma 4 Is Now Available on Docker HubDocker
 Llama 4 Maverick 17B Instruct API & PricingVercel
Webinar On DemandGet AI spend under control: A conversation with 1Password's CFO and Advisory CISO1password
