
Repetition Mismatch: Why Data Mixture Experiments Don’t Scale and How to Fix Them
Pre-training data mixtures are commonly tuned by running small-scale experiments and extrapolating to the target training budget.
 Cloud Security Trends & Challenges: Complete GuideCybersecurity Exchange
 How we grew Mintlify by doing things that don't scaleMintlify
 State of Speech: Our New Data Report Reveals ASR’s Untapped Potential - Deepgram Blog ⚡️Deepgram
 Build a Presentation Coaching Application with Recall - Deepgram Blog ⚡️Deepgram
 The Most Important Work in AI Training Is Also the Most Overlooked - Deepgram Blog ⚡️Deepgram
 Data Ingestion: 6 Ways to Speed Up Your ApplicationRedis
 How to Conduct an AI Agent Security Audit [+ Checklist]Zapier
 How to implement AI training for employeesZapier
 Plumsail Documents: Zapier spp spotlightZapier
 5 ways to automate Browse AIZapier
 How to connect Google Sheets to NotionZapier
 Pancakes Are Delicious and Data Centers Are for Free StuffThenewstack
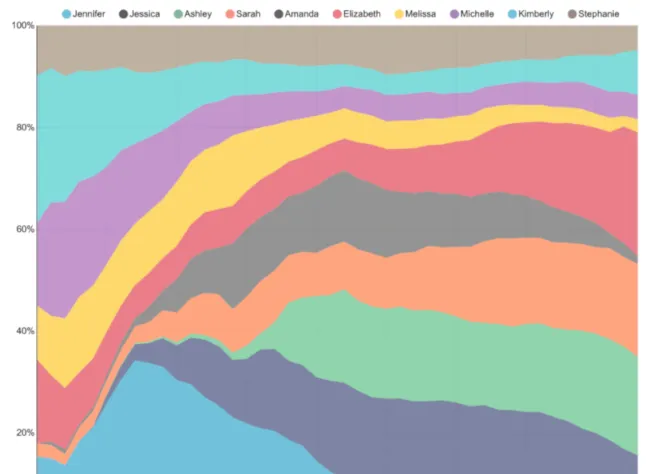 Explore and Visualize Data the Apache Superset WayThenewstack
 Transform and Future-Proof Your Architecture with MACHThenewstack
