
How to query Apache Arrow with chDB - ClickHouse Documentation
Setup Let’s first create a virtual environment:ipython to run the commands in the rest of the guide, which you can launch by running: Creating an Apache Arrow table from a file Let’s first download one of the Parquet files for the Ookla dataset, using the AWS CLI tool: If you want to download more files, use aws s3 ls to get a list of all the files and then update the above command.pyarrow package: shape attribute:…
 DataStore Query building - ClickHouse DocumentationClickhouse
How to query Parquet files - ClickHouse DocumentationClickhouse
How to query a remote ClickHouse server - ClickHouse DocumentationClickhouse
Formats for input and output data - ClickHouse DocumentationClickhouse
DataStore accessors - ClickHouse DocumentationClickhouse
Embedded in ClickHouse - ClickHouse DocumentationClickhouse
 Redirects - MintlifyMintlify
 Breaking down common documentation mistakesMintlify
 Mintlify Alternatives: What to Consider (and Why There's No True Substitute)Mintlify
 Format text - MintlifyMintlify
 OData or GraphQL? The Best Tech for Developing an API Is Neither or Both!Thenewstack
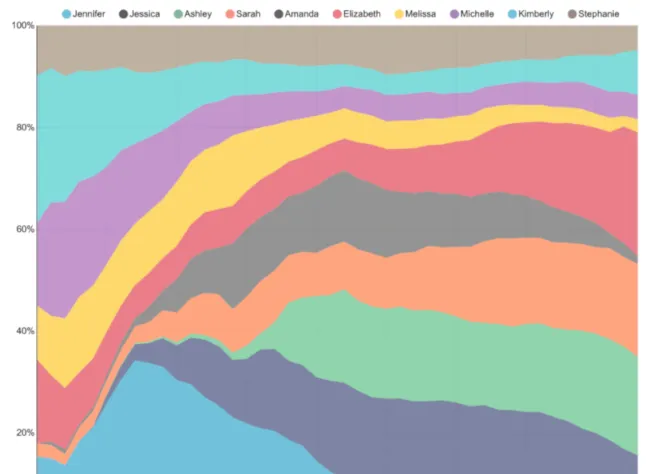 Explore and Visualize Data the Apache Superset WayThenewstack
 CLI ReferenceModal
 Analyze JSON Data Using SQL and DuckDBMotherduck
 Building a Remote MCP Server: OAuth, Tool Design & Lessons from 4,000+ AI Queries | MotherDuckMotherduck
 It's Ducking Easy: From Zero to Insight with MotherDuck and dbtMotherduck
 skill.md - MintlifyMintlify
 AsyncAPI setup - MintlifyMintlify
 Best Documentation Platforms for AI Agents in 2026Mintlify
 Best Docusaurus Alternatives in 2026Mintlify
