
Deploy a Text-to-Music Model - fal
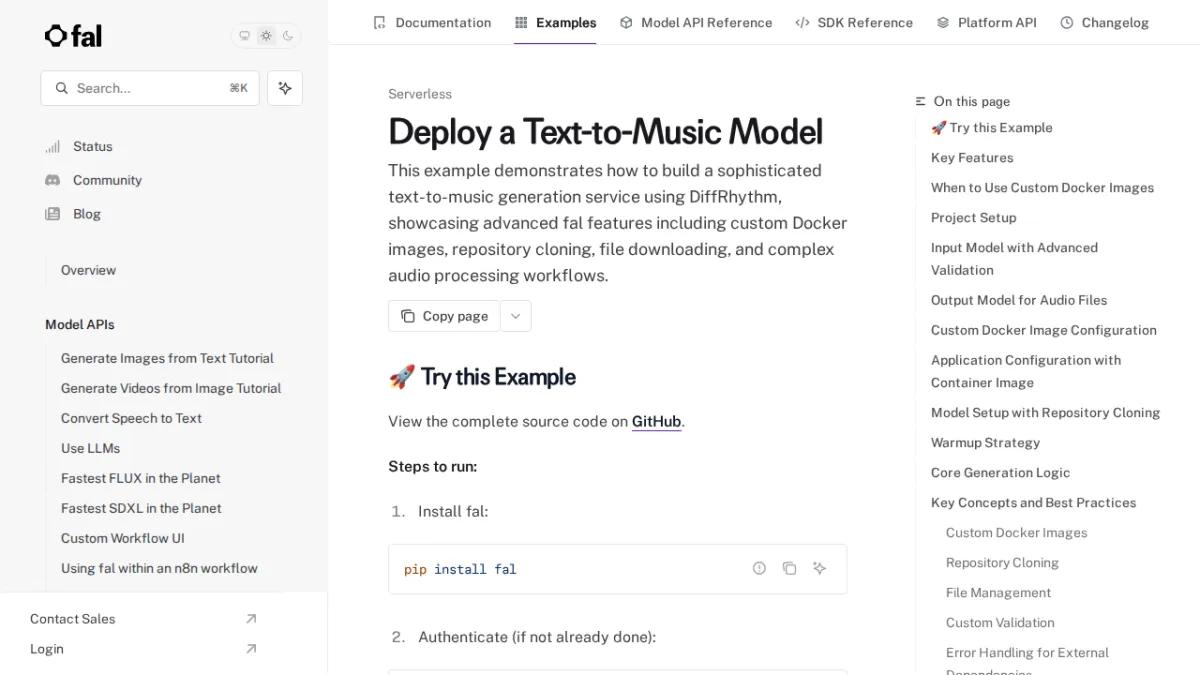
This example demonstrates how to build a sophisticated text-to-music generation service using DiffRhythm, showcasing advanced fal features including custom Docker images, repository cloning, file downloading, and complex audio processing workflows.
 How To Make a Character Replacement Video [2026]Fal
Luma Dream Machine: Text-to-Video AIFal
Kling 1.0 (Text to Video) API on falFal
Lightning Models (Text to Image) API on falFal
FLUX.1 [pro] (Text to Image) API on falFal
tripo3d/tripo/v2.5/text-to-3dFal
 Format text - MintlifyMintlify
 Top 3 Use Cases for Speech-to-Text in Gaming - Deepgram Blog ⚡️Deepgram
 Tagalog Speech to TextDeepgram
 New Spanish and Turkish Language Models and Updated General Models - Deepgram Blog ⚡️Deepgram
 Looping by Zapier: Repeat actions for itemsZapier
 Connect Any Git or Mercurial Repo to Pulumi with Custom VCSPulumi
 The Go Memory Model - The Go Programming LanguageGo
 What is a CUDA Thread Block?Modal
 CLI ReferenceModal
 How Hunch supercharged AI workflows with Modal SandboxesModal
 4 Ways to Animate the Color of a Text Link on HoverCss Tricks
 Memo-ry: Simplifying Daily Tasks for People with Memory Loss - CerebrasCerebras
 How AI Assistants Can Decode GitHub Repos for UI WritersDocker
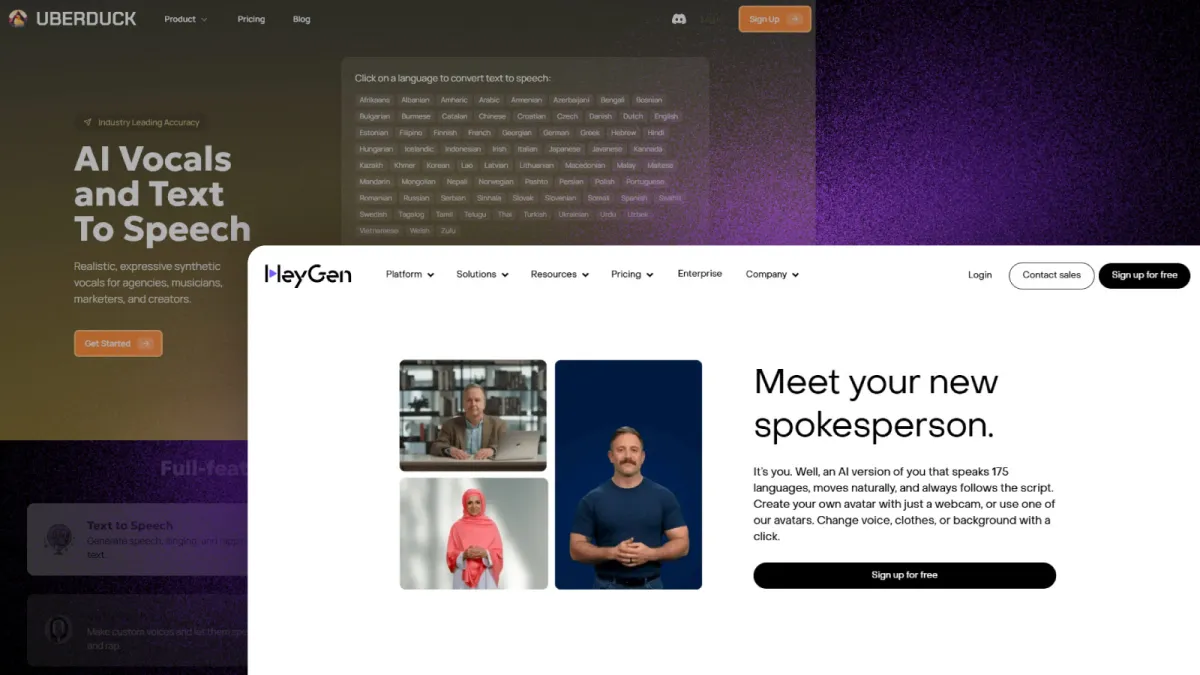 12 Best Uberduck Alternatives for AI Text-to-Speech GenerationHeygen
