
How to capture background requests and responses in Playwright?
Learn how to capture background requests and responses in Playwright using page request and response events with a practical Python example.
 How to ignore non-HTML URLs when web crawling?ScrapingBee
Does Guzzle use cURL?ScrapingBee
How to get file type of an URL in Python?ScrapingBee
Zapier | ScrapingBeeScrapingBee
Walmart API | ScrapingBeeScrapingBee
How to Ignore SSL Certificate Errors with Guzzle?ScrapingBee
 How automation helped us get better customer reviewsZapier
 What is a Load/Store Unit?Modal
 GraphQL setup - MintlifyMintlify
 Dynamic Data Capture Sets the Stage for Extreme PersonalizationThenewstack
 Enhancing Pulumi Copilot: Introducing System Prompts for Your OrganizationPulumi
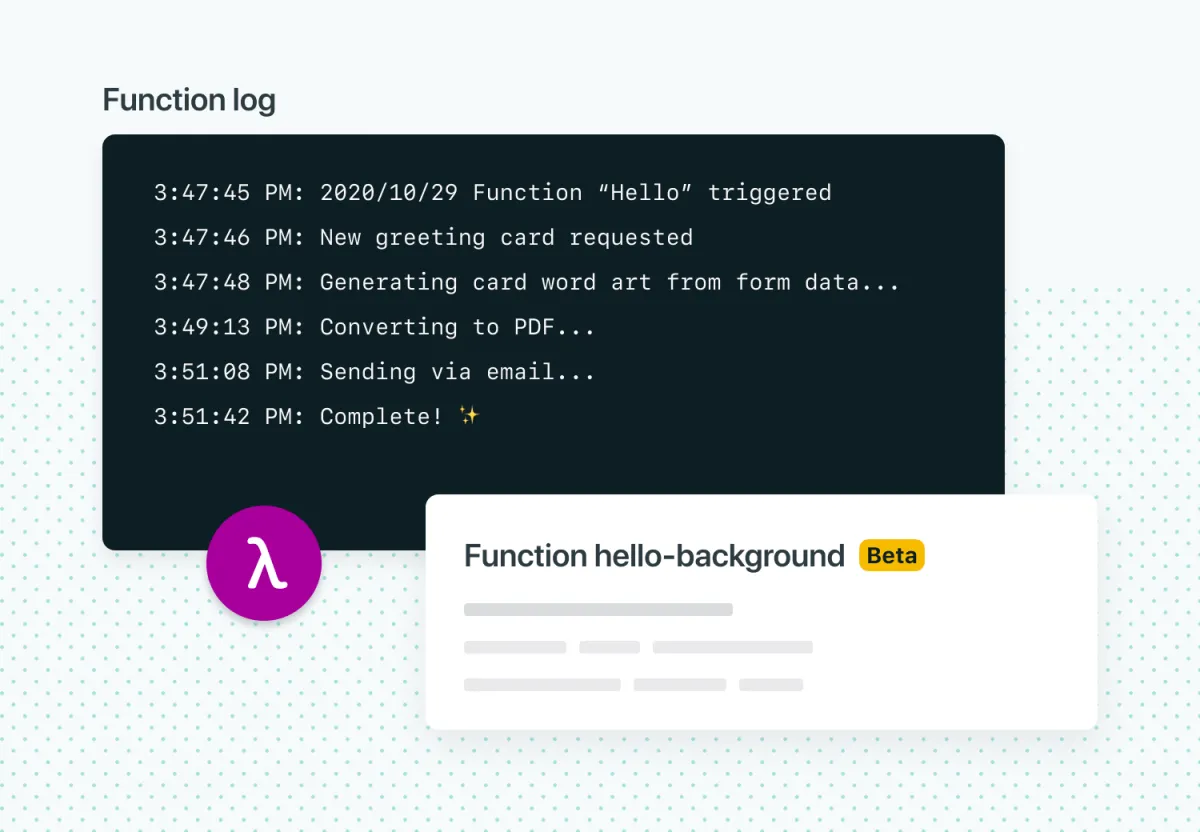 Netlify Background FunctionsCss Tricks
 Docker State of App Dev - Dev Ex & ProductivityDocker
 Introducing Origin Shield Concurrency Limits and QueueingBunny
 Improving video uploads: Introducing the Bunny Stream resumable & pre-signed APIBunny
 Vercel QueuesVercel
 OpenAI Chat Completions Structured Outputs with AI GatewayVercel
 Review changes - MintlifyMintlify
 Configure the assistant - MintlifyMintlify
 HTTP instrumentation configurationOpentelemetry
