
Announcing Together Inference Engine 2.0 with new Turbo and Lite endpoints
The Together Inference Engine achieves over 400 tokens per second on Meta Llama 3 8 B by building on the latest advances from Together AI, including Flash Attention-3, faster GEMM & MHA kernels, innovations in quality-preserving quantization, and speculative decoding.
 Announcing the New Pulumi Partner ProgramPulumi
 Announcing Restore Stacks: Recover Deleted Stacks in the Pulumi CloudPulumi
 Pkg.go.dev has a new look! - The Go Programming LanguageGo
The App Engine SDK and workspaces (GOPATH) - The Go Programming LanguageGo
Go on App Engine: tools, tests, and concurrency - The Go Programming LanguageGo
Go.dev: a new hub for Go developers - The Go Programming LanguageGo
 The rise of slow personal assistantsCerebras
 Real-Time Computational Physics with Wafer-Scale Processing [updated]Cerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
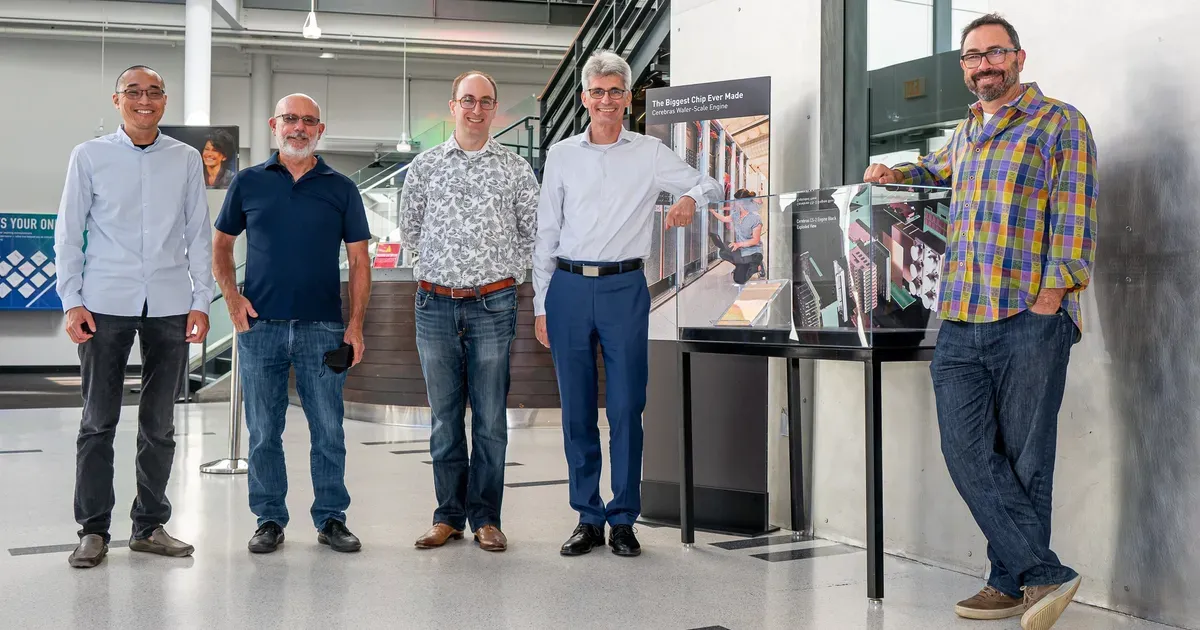 Cerebras Wafer-Scale Engine Inducted into the Computer History Museum - CerebrasCerebras
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
 AMD and Cerebras Announce Disaggregated AI InferenceCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
