
Blogs
Introducing AutoJudge: Streamlined inference acceleration via automated dataset curation
We introduce Auto Judge, a method that accelerates large language model (LLM) inference through task-specific lossy speculative decoding.
 Docs-as-code solutions for API teams: how to choose the right platform in 2026Mintlify
 Calling Your Video Game With Your Phone: Part 1Deepgram
 How a marketing agency increased client conversions 35% with Zapier CanvasZapier
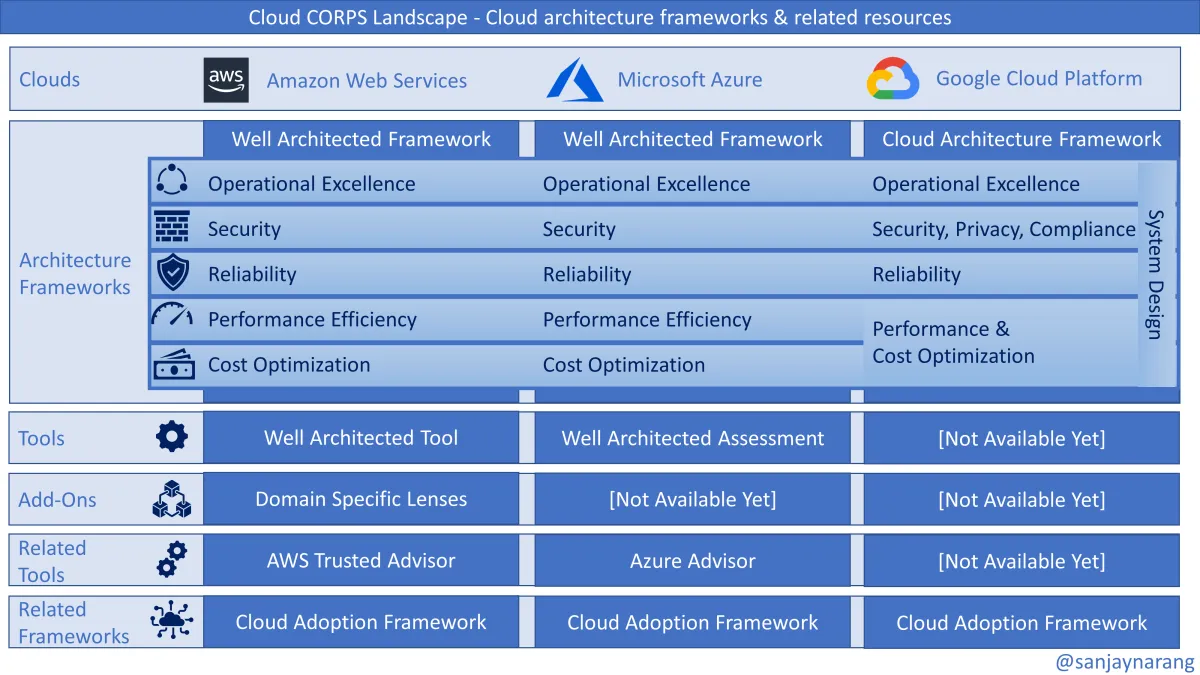 Introducing CORPS: The 5 Pillars for a Robust Cloud Architecture FrameworkThenewstack
 Introducing New Slimmer Docker ImagesPulumi
 How Ramp automated receipt processing with fine-tuned LLMsModal
 Introducing: H100s on ModalModal
 pg_duckdb: Splicing Duck and Elephant DNAMotherduck
 The Serverless Backend for Analytics: Introducing MotherDuck’s Native Integration on VercelMotherduck
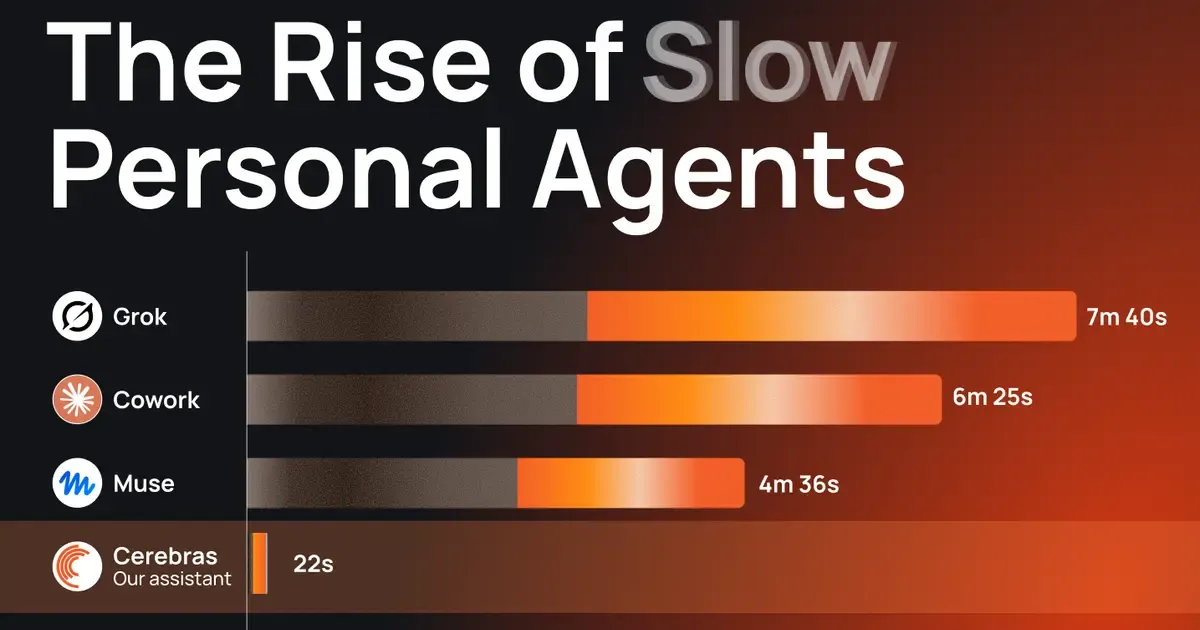 The rise of slow personal assistantsCerebras
 Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
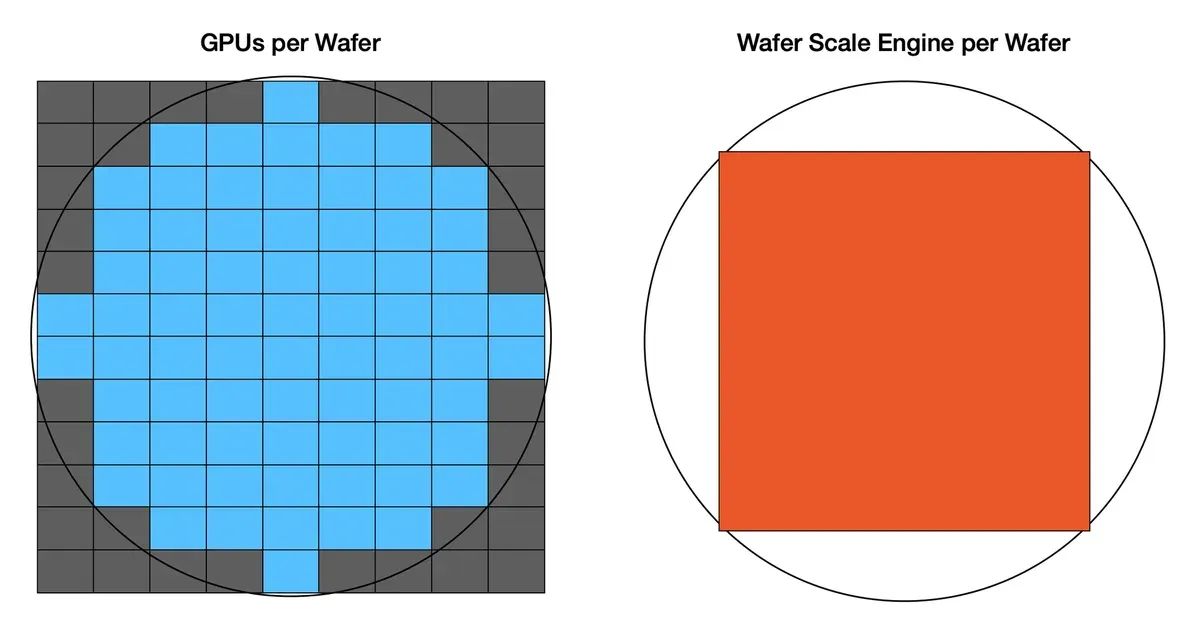 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
