
Benchmarking inference at scale: coding agents
On a production coding agent workload, Together Inference Engine delivers 31% more TPS than the next fastest OSS engine on the same hardware, and maintains 2× better TTFT at saturation.
 How we grew Mintlify by doing things that don't scaleMintlify
 10 best AI observability tools for monitoring and evaluating agents in 2026Mintlify
 How to implement AI training for employeesZapier
 Pancakes Are Delicious and Data Centers Are for Free StuffThenewstack
 Transform and Future-Proof Your Architecture with MACHThenewstack
 Selecting the Right Database for Your MicroservicesThenewstack
 Pulumi Neo Now Supports AGENTS.mdPulumi
 How to serve trillions of tokens for trillion-parameter coding agentsModal
 Do AI Agents Need a Semantic Layer?Motherduck
 Building a Remote MCP Server: OAuth, Tool Design & Lessons from 4,000+ AI Queries | MotherDuckMotherduck
 The rise of slow personal assistantsCerebras
 Real-Time Computational Physics with Wafer-Scale Processing [updated]Cerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
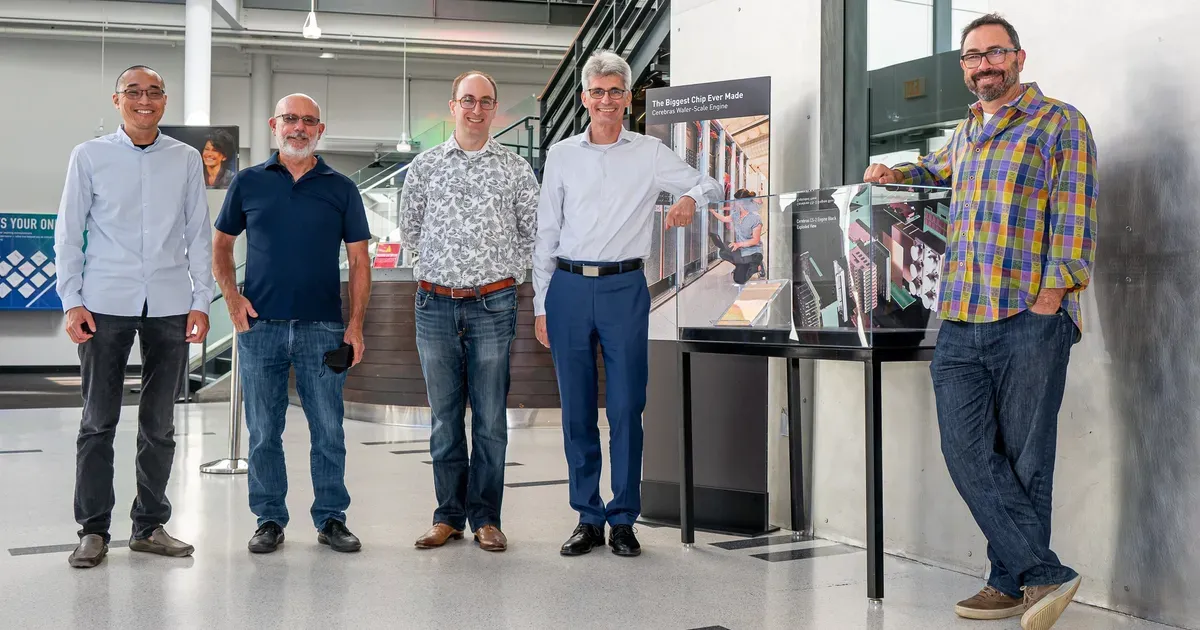 Cerebras Wafer-Scale Engine Inducted into the Computer History Museum - CerebrasCerebras
