
Blogs
How speech models fail where it matters the most and what to do about it
We demonstrate that voice recognition systems struggle to understand street name pronunciations when speakers have diverse linguistic backgrounds — with an average transcription error rate of 39% across 15 state-of-the-art models, and an 18% accuracy gap between non-English and English primary speakers.
 Cloud Security Trends & Challenges: Complete GuideCybersecurity Exchange
 Digital Forensics & Emerging Technologies GuideCybersecurity Exchange
 How we grew Mintlify by doing things that don't scaleMintlify
 10 best AI observability tools for monitoring and evaluating agents in 2026Mintlify
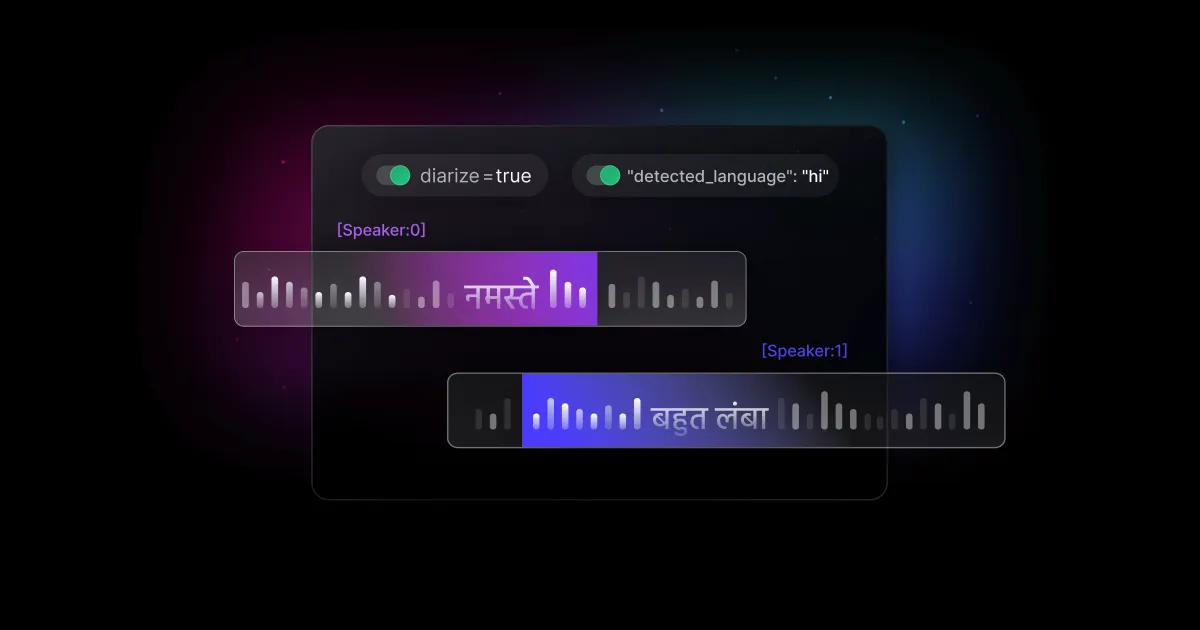 Trained on 100,000+ Voices: Deepgram Unveils Next-Gen Speaker Diarization and Language DetectionDeepgram
 State of Speech: Our New Data Report Reveals ASR’s Untapped Potential - Deepgram Blog ⚡️Deepgram
 Who Explains the Most? An Analysis of Educational YouTubers - Deepgram Blog ⚡️Deepgram
 The Language of LGBTQ Inclusion and Allyship - Deepgram Blog ⚡️Deepgram
 Top 3 Use Cases for Speech-to-Text in Gaming - Deepgram Blog ⚡️Deepgram
 Q&A with Deepgram’s New CPO, Ed AnuffDeepgram
 Mind the Gap: The Chasm Between AI Fiction and Fact - Deepgram Blog ⚡️Deepgram
 Tagalog Speech to TextDeepgram
 The Most Important Work in AI Training Is Also the Most Overlooked - Deepgram Blog ⚡️Deepgram
 New Spanish and Turkish Language Models and Updated General Models - Deepgram Blog ⚡️Deepgram
