
Blogs
Together Evaluations: Benchmark Models for Your Tasks
When building products with large language models, knowing how well a model can solve your task is crucial, especially with the rapid rate at which new LLMs appear.
 10 best AI observability tools for monitoring and evaluating agents in 2026Mintlify
 New Spanish and Turkish Language Models and Updated General Models - Deepgram Blog ⚡️Deepgram
 AI frameworks: Definition, types, and how to chooseZapier
 Discovered Stacks: One Place for All Your InfrastructurePulumi
 How Hunch supercharged AI workflows with Modal SandboxesModal
 Anthropic integration with Modal brings scalable compute to Claude ScienceModal
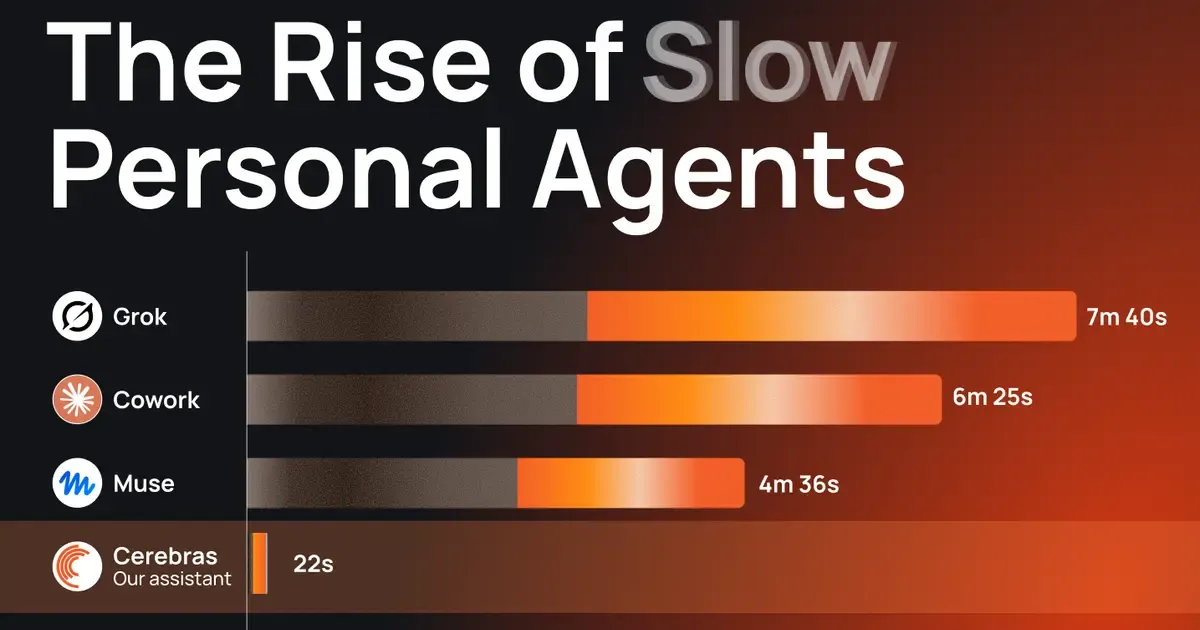 The rise of slow personal assistantsCerebras
 Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Cerebras Systems Enables GPU-Impossible™ Long Sequence Lengths Improving Accuracy in NaturalCerebras
Memo-ry: Simplifying Daily Tasks for People with Memory Loss - CerebrasCerebras
 How to Run Hugging Face Models Programmatically Using Ollama and TestcontainersDocker
 API docs with Git integration: best platforms and workflows in 2026Mintlify
 Lies, damn lies, and benchmarksDeepgram
 How Basecamp Uses Basecamp 3 to Manage Team Projects and Simplify CommunicationZapier
