
Blogs
Introducing preemptible compute: the same compute, half the price
Preemptible nodes give teams a lower-cost way to run interruption-tolerant work — short experiments, inference bursts, batch jobs — on the same GPU infrastructure they already use, billed sub-hourly at a flat 50% of the on-demand rate.
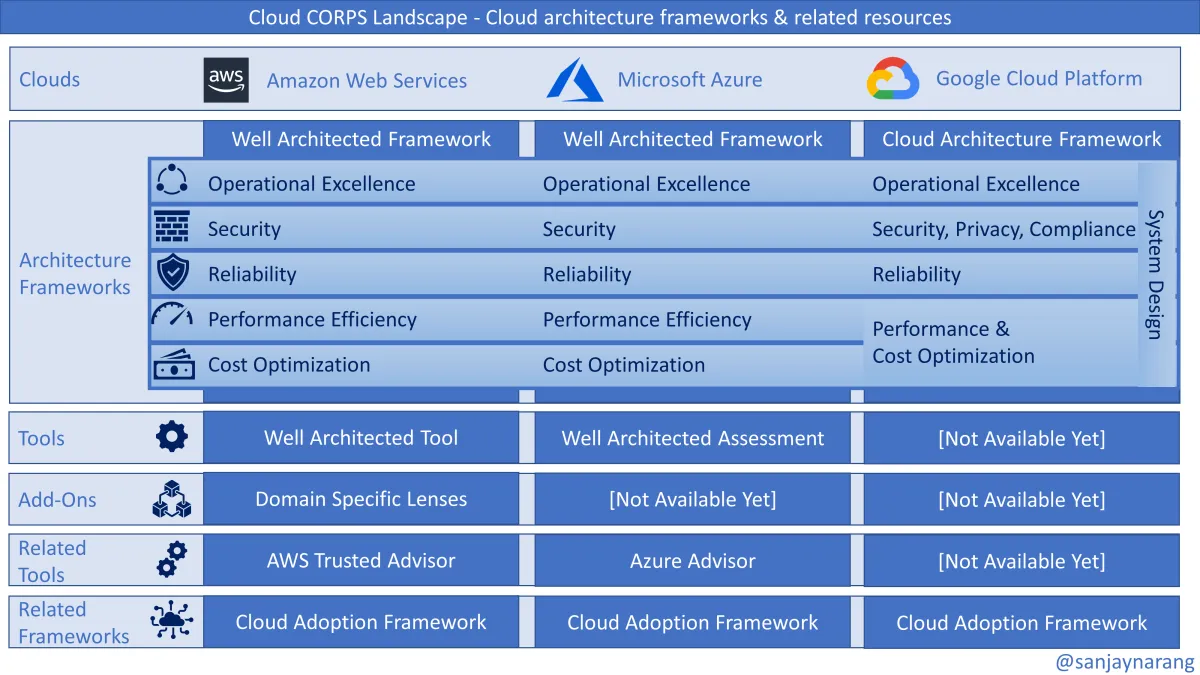 Introducing CORPS: The 5 Pillars for a Robust Cloud Architecture FrameworkThenewstack
 Pulumi Neo Now Supports AGENTS.mdPulumi
 Introducing New Slimmer Docker ImagesPulumi
 The Go Memory Model - The Go Programming LanguageGo
 Sidecars: A low-latency trust boundary for SandboxesModal
 Introducing: H100s on ModalModal
 Anthropic integration with Modal brings scalable compute to Claude ScienceModal
 Creating Color Themes With Custom Properties, HSL, and a Little calc()Css Tricks
 pg_duckdb: Splicing Duck and Elephant DNAMotherduck
 Do AI Agents Need a Semantic Layer?Motherduck
 The Serverless Backend for Analytics: Introducing MotherDuck’s Native Integration on VercelMotherduck
 Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Cerebras Systems Enables GPU-Impossible™ Long Sequence Lengths Improving Accuracy in NaturalCerebras
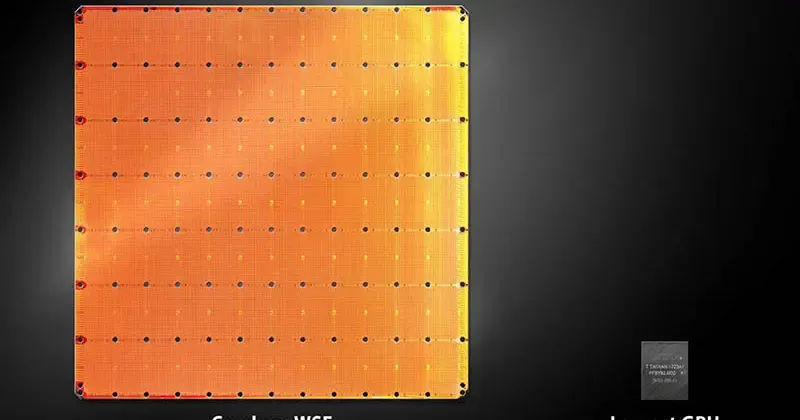 Cerebras Systems Unveils the Industry’s First Trillion Transistor Chip - CerebrasCerebras
