
Two Misconfigurations That Caused Spark OOM Failures on Kubernetes
After migrating Spark pipelines to Azure Kubernetes Service, two infrastructure settings interacted destructively: spark.kubernetes.local.dirs.tmpfs=true backed shuffle spill with RAM instead of disk, and a hard podAffinity rule forced all executors onto one node.
 Stragglers, Not Failures: How Adaptive Hedged Requests Reduce p99 Latency by 74 PercentInfoq
 Kubernetes Operators in DepthInfoq
Grab Redesigns Counter Service Storage for 50% Lower P99 LatencyInfoq
The Async Multiprocessing Has Sound Foundations in Linux, But Further Testing is NeededInfoq
AI Agents with Cloud Credentials Are Outrunning Billing Guardrails Built for Human-Speed MistakesInfoq
How to Develop Software Engineering Skills in the Age of AIInfoq
 Local Kubernetes Development Using Minikube and Redis EnterpriseRedis
 How to connect Google Sheets to NotionZapier
 How Argo CD and OpenShift Enable GitOps for DevelopersThenewstack
 Google Anthos from the Eyes of a Kubernetes DeveloperThenewstack
 Lessons Swift Designer Chris Lattner Has Learned about LeadershipThenewstack
 Security Considerations for API-Driven Apps Deployed to CloudThenewstack
 AWS Enterprise Container Management with PulumiPulumi
 Supporting Kubernetes with Faster, Easier Test EnvironmentsPulumi
 Neo Integrations: MCP Servers and Cloud CLIsPulumi
 Multiple Class / ID and Class SelectorsCss Tricks
 Real-Time Computational Physics with Wafer-Scale Processing [updated]Cerebras
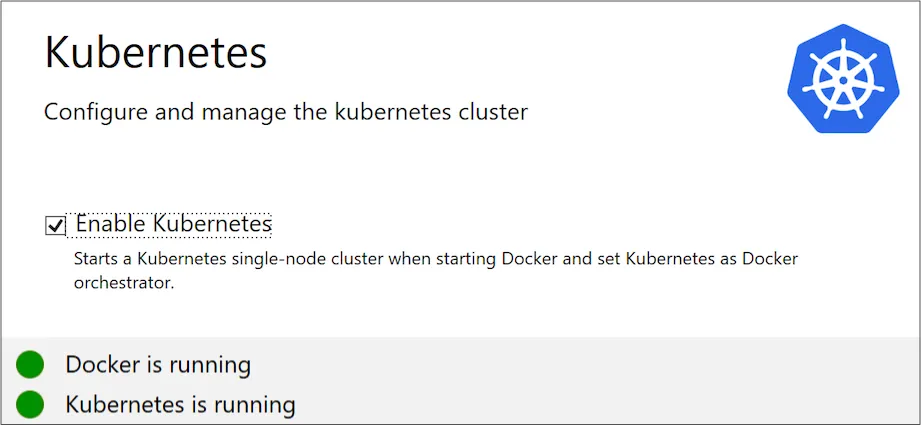 Docker for Windows Desktop with KubernetesDocker
 Two-factor AuthenticationVercel
 Hands-on: Create Your First Serverless Application in Apache OpenWhiskThenewstack
