
Training: Fine-tuning, RL, and multi-node GPUs
Manage rollouts, evals, and clustered training from a single file. On-demand access to single and multi-node GPUs, including RDMA-enabled clusters.
 Dedicated EndpointsModal
Fine-tuning a FLUX.1-dev style LoRAModal
Glossary: LLM fine-tuning hyperparametersModal
How much VRAM do I need for LLM model fine-tuning?Modal
Create a custom video generator by fine-tuning a Mochi LoRA on ModalModal
LoRA vs. QLoRA: Efficient fine-tuning techniques for LLMsModal
 The Most Important Work in AI Training Is Also the Most Overlooked - Deepgram Blog ⚡️Deepgram
 How to implement AI training for employeesZapier
 AI frameworks: Definition, types, and how to chooseZapier
 How Ramp automated receipt processing with fine-tuned LLMsModal
 Introducing: H100s on ModalModal
 What is a Streaming Multiprocessor?Modal
 Simulating Human Behavior with Cerebras - CerebrasCerebras
 KAUST and Cerebras Named Gordon Bell Award Finalist for Solving Multi-Dimensional SeismicCerebras
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
 Cerebras Systems Raises $250M in Funding for Over $4B Valuation to Advance the Future of ArtificialCerebras
 with Docker Using Node.jsDocker
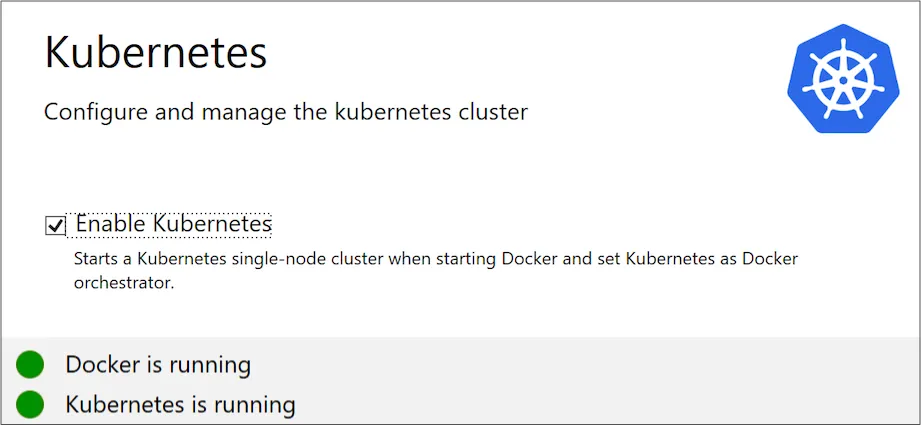 Docker for Windows Desktop with KubernetesDocker
